country_code

MD Anderson Researchers Harness AI to Transform Cancer Care

Scientists from the leading cancer center tap into the power of AI as they reshape their approach to data.
by
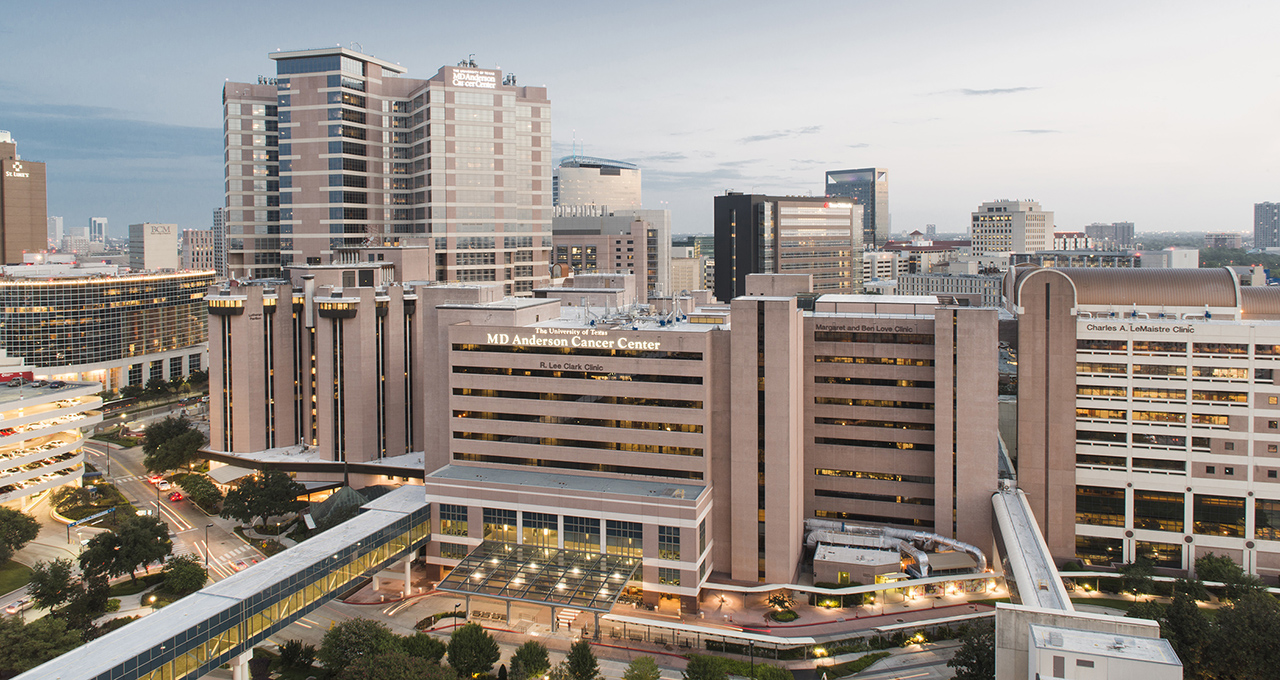
Houston Medical Center and MD Anderson sunrise

To unlock real insights from data, AI and data science research can’t live on the outskirts of an institution — it has to become part of an organization’s core strategy.

The University of Texas MD Anderson Cancer Center, the top-ranked cancer hospital in the U.S., is doing just that, with a new focus on data governance and dozens of researchers pursuing AI-accelerated oncology projects to improve patient care.

“We are focusing on the data in context, ensuring we have a coordinated metadata supply chain to address the current challenges in making AI models translate to impact in the clinic,” said Dr. Caroline Chung, who was recently appointed MD Anderson’s first chief data officer. “To build better and more robust predictive models, we need a coordinated strategy that covers every step from data generation to the clinical use of machine learning insights.”

This data governance strategy will influence the way hospital data is collected and used for insight generation, and enable findability, accessibility, interoperability and reusability of the data.

“It’s a big culture change,” said Chung. “The more data we can capture with contextual information, the more complex questions we can ask and the greater potential we have to use machine learning insights to help our clinicians improve their interactions with patients to guide the data-driven treatment decisions with the best patient outcomes aligned with the goals of care.”

By building a pipeline that collects the high-quality data researchers need, stores it securely and tracks how it’s being used, MD Anderson aims to better support projects to help clinicians analyze radiology data, deliver cancer treatment and predict complications like sepsis.

Many of these projects are already underway, accelerated by the speed of new GPU-powered technologies, such as NVIDIA DGX systems. New investments coming online at MD Anderson will give researchers access to thousands of additional GPU cores to support AI projects across the institution.

Applying AI to Diagnostic Imaging 

The first step in oncology is detecting tumors — the earlier the better. MD Anderson is developing early detection AI applications to help diagnose patients with pancreatic cancer, which has a five-year survival rate of just 10 percent.

“Pancreatic cancer is often diagnosed after it’s already metastasized, meaning it’s spread to other organs,” said Dr. Eugene Koay, co-director of Gastrointestinal Radiation Oncology at MD Anderson. “We’re working on AI models to analyze the pancreas anytime we see it in a CT scan, MRI study or endoscopic ultrasound, whether or not the patient’s appointment is related to the pancreas.”

Not all pancreatic tumors are the same. Some are slow moving, others are aggressive. Some originate from cysts in the pancreas, others don’t.

In collaboration with the Early Detection Research Network, Koay and his team are working on convolutional neural networks that identify which cases are most likely to develop into malignant cancer, so clinicians can better support patients at risk.

Imaging Insights Inform Treatment Planning 

When preparing for radiation therapy to treat cancerous cells, oncologists rely on a process known as contouring to trace the tumors that will be targeted by radiation treatment.

It’s a time-consuming process, and oncologists often have a backlog of radiotherapy treatment plans to create for patients. Dr. Laurence Court, associate professor of Radiation Physics at MD Anderson, hopes to reduce the burden of manual contouring with AI tools, enabling hospitals to treat thousands more cancer patients each year.

He’s especially interested in the impact these AI clinical tools could have in low-resource settings, where a shortage of radiologists and oncologists makes it harder to access lifesaving radiotherapy treatments.

Contouring is also used to plan for MRI-assisted radiosurgery, an advanced form of brachytherapy in which a radiation dose is delivered to cancerous tissue through implanted seeds. MD Anderson radiation oncologist Dr. Steven Frank uses this therapy to treat prostate cancer.

Precise contouring of the prostate and surrounding organs on MRI ensures that radioactive seeds are delivered to the right areas to treat the cancer without harming neighboring tissues.

By adopting an AI model that uses advances in GPU technologies, MD Anderson oncologists have improved the quality of contours for brachytherapy treatment planning and treatment quality assessment, said Dr. Jeremiah Sanders, a medical imaging physics fellow at MD Anderson who’s developing translational AI in Frank’s lab.

Sanders and Frank are also working on a model for use after a brachytherapy procedure — an AI application that analyzes MRI studies of the prostate to determine the quality of the radiation delivery. Insights from this model can help clinicians determine if additional treatment is needed and how to manage patients after their treatments.

Keeping a Watchful AI on Model Accuracy

For an AI model to succeed in a clinical setting, medical researchers need to catch the cases where the neural network struggles and retrain it to improve the application’s performance.

Dr. Kristy Brock, professor of Imaging Physics and Radiation Physics at MD Anderson, is working on an anomaly detection project to determine the cases where an AI model that contours liver tumors from CT scans fails — such as unusual images where a patient has a stent in the liver or fluid around the organ.

By identifying these rare failures, researchers can introduce additional training examples that are similar to cases the neural network previously stumbled on. This continuous training method selectively bolsters training data to improve model performance more efficiently.

“We don’t want to keep collecting data that looks the same as our first 150 scans,” Brock said. “We want to identify cases that will increase the variability of our sample dataset, which in turn boosts the model’s accuracy and generalizability.”

MD Anderson is one of several leading healthcare institutions adopting AI to improve medical research and patient care. Learn more about AI in healthcare at NVIDIA GTC, running online through Nov. 11.

Tune in to a healthcare special address by Kimberly Powell, NVIDIA’s VP of healthcare, on Nov. 9 at 10:30am Pacific. Watch NVIDIA founder and CEO Jensen Huang’s GTC keynote address below. Subscribe to NVIDIA healthcare news here.
From Training to Production, NVIDIA and CoreWeave Close the Loop on Agentic AI

NVIDIA Vera Rubin NVL72 and Vera CPU on CoreWeave accelerate agentic AI for companies including Cognition, extending a nearly decade-long run on NVIDIA infrastructure that stays productive, durable and fungible across generations.
by

Building on nearly a decade of co-engineering, CoreWeave has built NVIDIA compute, networking and software into a cloud purpose-built for AI that’s still returning on investment across multiple generations of deployment. Now, CoreWeave is bringing the next generation of NVIDIA infrastructure to production.

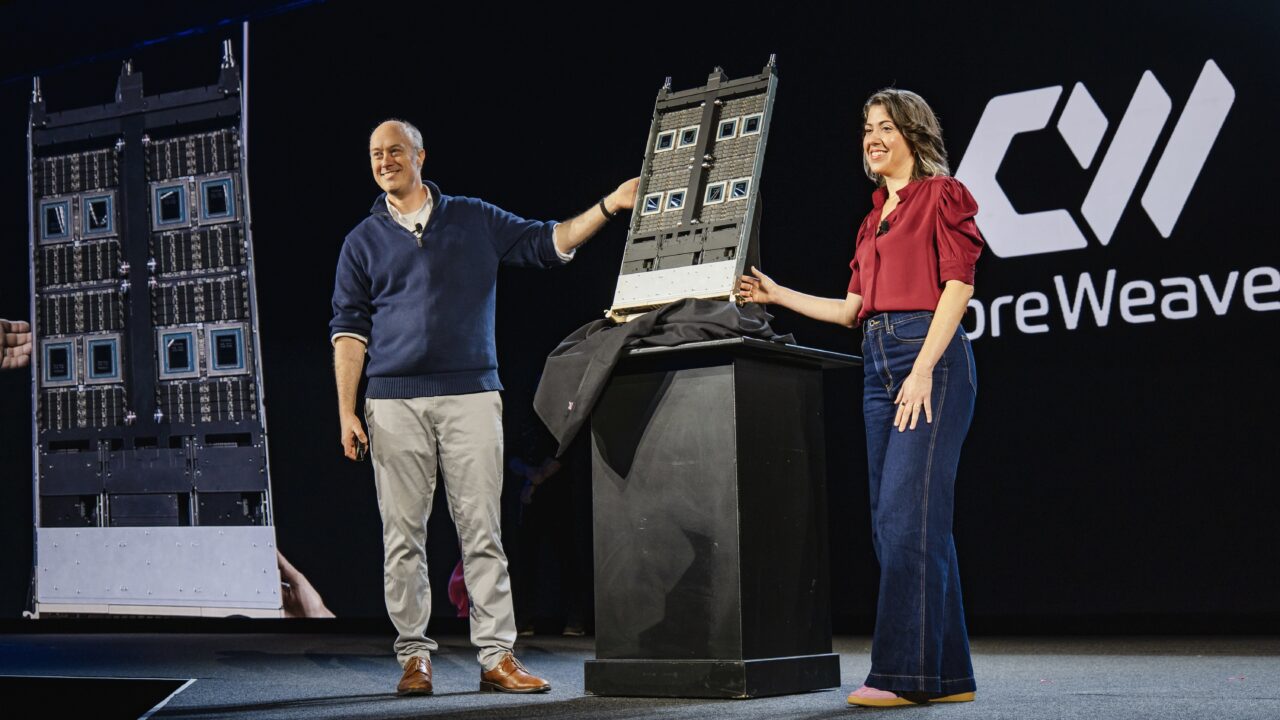
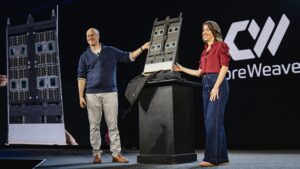
At CoreWeave Fully Connected, running this week in San Francisco, CoreWeave announced availability of NVIDIA Vera Rubin NVL72 systems with Spectrum-X 102.4T Ethernet networking. Cognition, the applied AI lab behind the Devin AI software engineer, is the first customer running production workloads on Vera Rubin. 

CoreWeave will also offer NVIDIA Vera, the first CPU built for AI agents. In addition, CoreWeave launched CoreWeave Forge, a connected environment for training, evaluating and improving models and agents on NVIDIA accelerated computing.

“NVIDIA accelerated computing delivers value across generations,” said Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA. “CoreWeave’s NVIDIA V100 GPUs are still running customer workloads nearly a decade after Volta launched, even as CoreWeave brings Vera Rubin NVL72 into production. That’s the strength of the NVIDIA platform: infrastructure that keeps earning for years, and the flexibility to put the right GPU on the right workload.”

Cognition Runs on Vera Rubin NVL72 With 4.8x Higher Token Throughput

Cognition runs training, reinforcement learning and production inference for Devin on CoreWeave. The company scaled to thousands of GPUs on CoreWeave in nine months, powering Cognition inference workloads.

Earlier this month, CoreWeave received its first Vera Rubin NVL72 production racks. Shortly after, Cognition benchmarked Vera Rubin’s inference performance against a GB200 NVL72 baseline using a real-world software engineering workload. To generate this workload, it sampled a subset of tasks from FrontierCode and deployed AI agents to solve them.  

In its early tests, Cognition saw Vera Rubin NVL72 deliver up to a 4.8x increase in total token throughput for SWE-2 inference workloads over GB200 NVL72. For Devin, those gains mean faster real-time code generation and more responsive multistep reasoning.

“Agentic coding is a complex workload: long contexts, high concurrency and token volumes where cost per token decides what we can ship,” said Silas Alberti, founding team at Cognition. “Having all of it on one platform, with NVIDIA and CoreWeave engineers who work the hard problems alongside ours, matters more to us than any single spec.”

CoreWeave Announces NVIDIA Vera Rubin Availability on CoreWeave Cloud

CoreWeave announced availability of NVIDIA Vera Rubin NVL72 on CoreWeave Cloud, making it one of the first cloud providers to deliver the platform in customers’ hands.

Early-access customers can put the performance of NVIDIA’s full-stack AI factory platform to work quickly on CoreWeave Cloud. In days, CoreWeave stood up a production Vera Rubin cluster for Cognition, achieved as a result of the codesign and collaboration between NVIDIA and CoreWeave up and down the stack, from infrastructure to tokens served. 

Capacity can be operated through CoreWeave Kubernetes Service, SUNK, CoreWeave Mission Control, CoreWeave Sandboxes and CoreWeave Inference. 

NVIDIA Vera CPU to Come to CoreWeave Cloud, Tests Show More Than 3x Faster Agentic Sandbox Startups

Agentic AI puts pressure on infrastructure from two directions: serving agents demands low-latency compute at scale, while improving them through post-training requires thousands of isolated environments running at once.

NVIDIA Vera CPU is purpose-built for agentic workloads. For agentic AI, a key performance measure is how many isolated agent environments can run at once and how consistent and performant each one stays as that number grows. 

CoreWeave’s deployment of Vera puts 128 CPUs and 11,264 cores in a single rack, enough for more than 11,000 concurrent environments at one core each. With CoreWeave Sandboxes, these environments are hardware-isolated and run alongside the training jobs they support, with Spectrum-X Ethernet switches and BlueField-4 DPUs ensuring secure, high-performance, secure agent communication at low latency. 

In testing, CoreWeave achieved more than 3x faster agent sandbox startup times on NVIDIA Vera CPUs, accelerating and scaling its sandboxes, an execution layer for reinforcement learning (RL), agent tool use and model evaluation that let AI teams run code in isolated environments on CoreWeave. On Terminal-Bench, CoreWeave saw a 1.7x performance gain on Vera CPU across all passing tasks.

CoreWeave Forge: Closing the AI Loop From Production Back to Training

Models and agents improve by running a loop: production behavior informs the next training run, and each evaluation sharpens the next version. This loop has historically been split across tools from different vendors, with signal lost at every handoff.

CoreWeave Forge unifies Weights & Biases, post-training expertise from OpenPipe and the open source marimo notebook project in one connected environment built for continuous model and agent improvement. It stays open across models, frameworks and clouds.

New and expanded capabilities available include:

  • CoreWeave ARIA — now generally available — helps users learn, research, code and iterate across the AI loop, analyzing runs, proposing experiments, recommending code changes and storing them in GitHub, and bringing back actionable evidence that analyzes experiment data, surfaces what drove a change and proposes the next experiments to run.
  • CoreWeave Agent Lens — a new service — turns production agent observability into continuous improvement and understandable insights. It improves failure detection by 20% and fixes issues at half of the cost, which turns tens of millions of production agent traces into insights that drive fixes.
  • CoreWeave Sandboxes — now generally available — let users run agents, tool calls, RL and evaluations in isolated CPU or GPU execution environments, on serverless infrastructure or on the infrastructure they already train on, providing a fresh, isolated environment for every agent tool call, RL run or evaluation.
  • Post-training improves model quality and cuts latency and costs harnessing users’ own production signals, with no training cluster required. Serverless supervised fine-tuning and serverless RL let users experiment with their own training recipes. Serverless RL trains 1.4x faster at 40% lower cost than a self-managed setup.

NVIDIA Dynamo, an open source inference framework for AI factories, powers CoreWeave’s managed inference service as well as RL Rollouts, now in private preview. RL Rollouts loads new checkpoints into a live deployment while it’s running, so reinforcement learning continues without redeploys, and post-training gets the same inference efficiency as production.

Canva, Capital One and MasterClass are among the first companies building on Forge.

NVIDIA Nemotron open models give teams on Forge a direct path to customizing and deploying reasoning and multimodal models for agentic workflows.

Proven Impact From Startups to Global Enterprises

AI labs, AI-natives and global enterprises are using the co-engineered NVIDIA and CoreWeave platform to move from prototype to production faster. 

In healthcare, Ennoble Care, a home-based care provider serving about 50,000 high-need Medicare patients across 15 states, selected CoreWeave to run clinical AI inference. It will use reserved NVIDIA RTX PRO 6000 GPU capacity on CoreWeave Kubernetes Service to scale AI agents for clinical documentation, decision support and back-office automation.

CoreWeave has delivered record MLPerf results in every round of training and inference. It’s the only cloud provider who holds the Platinum ranking in SemiAnalysis ClusterMAX 1.0, 2.0 and 3.0, and serves nine of the 10 leading AI labs.

Together, NVIDIA and CoreWeave are giving customers a platform to turn experimental agents into production systems that write software, support clinicians and do useful work in the real world.

Learn more by attending NVIDIA sessions, demos and workshops at CoreWeave Fully Connected.

Sakeena Fiza Helps NVIDIA Hardware Succeed at Scale

By testing systems from lab bring-up to production, validation engineers turn cutting-edge hardware into dependable infrastructure.
by

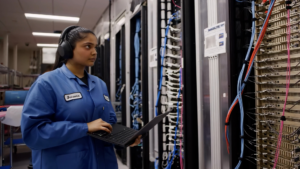
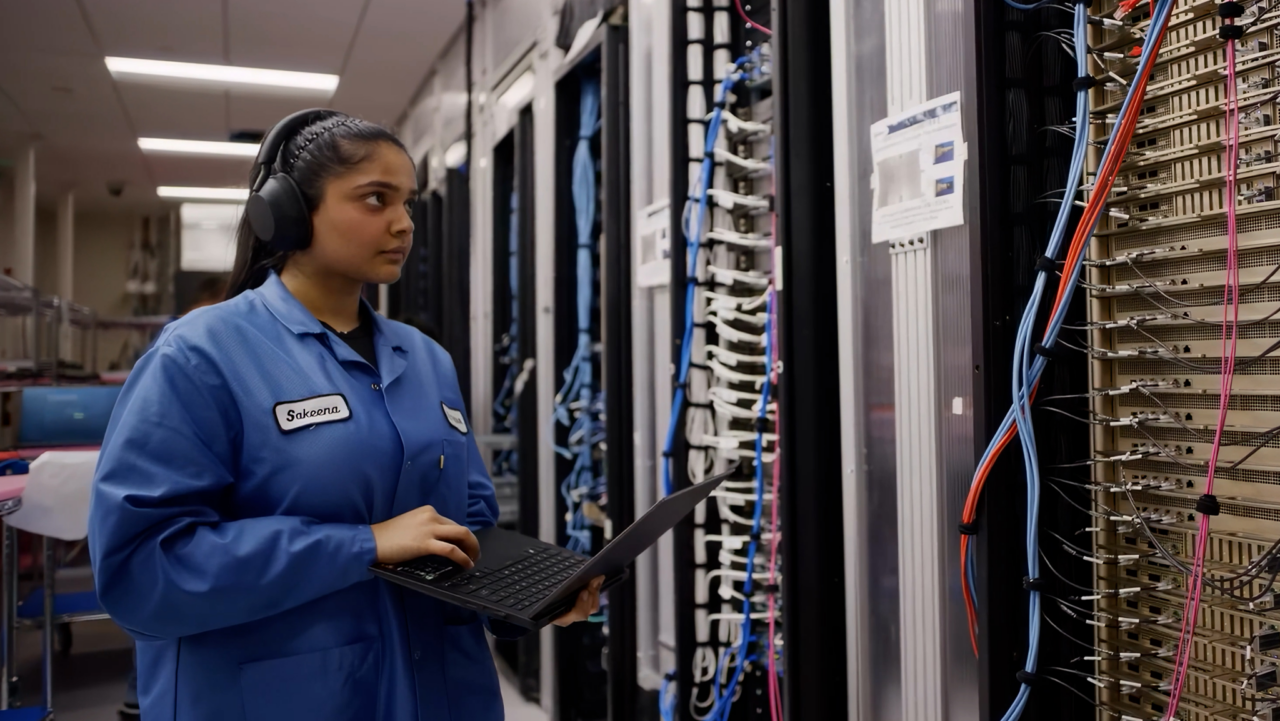
When Sakeena Fiza describes her work as a validation engineer at NVIDIA, she does so in terms more befitting a detective story than a world-class engineering lab.

“Validation engineers look in the shadows and shine a light into every corner,” Fiza said. “Every time we get a system, our first thought is: how can it break?”

And when it does? 

“I always like to think of it as a mystery to solve,” she said.

At NVIDIA, the systems Fiza and her colleagues in the data center systems engineering lab investigate are the engines of the AI era. Her work begins before the rest of the world knows a product exists — in the lab — when a new system first receives power.

Components are brought up one by one, boards are integrated, firmware and software teams swarm, and engineers watch for the first signs of life. 

One of Fiza’s earliest and most enduring memories of working at NVIDIA is the collective joy she experienced when she saw the NVIDIA Rubin GPU working for the first time at a system level.

“It literally just said, ‘NVIDIA Corporation Device,’” she recalls. “And everyone’s cheering and celebrating because it’s the first time in the world that a Rubin GPU enumerated at a system level.”

Those moments, electric as they are, are only the beginning. From there, the system must be made resilient: from tray to rack to cluster to production line to customer AI factory. 

Fiza describes validation — the process of ensuring a physical device works correctly before mass production begins — as becoming “the first customers for the product,” exercising hardware to its limits in a range of real-world conditions before anyone else has to depend on it.

“The goal is to always catch issues before customers catch it,” she said. 

Beyond the lab, Fiza and colleagues collaborate in coworking spaces across our Santa Clara offices.

Fiza arrived at NVIDIA after earning her bachelor’s degree at the University of California, Irvine, where she studied computer science and engineering. Her path into hardware was the result of an accumulating fascination with systems. 

Growing up in Dubai, she was introduced to coding via the Logo programming language, prompting future forays into systems design that included building Mars rovers at a high school robotics camp and working on unmanned aerial vehicles in college.

What drew her to work with data center systems was the chance to work with the whole machine. At NVIDIA, she said, validation sits at exactly that intersection: firmware, hardware, software, mechanical design, thermal behavior, manufacturing and customer experience.

“I get to be a mechanical engineer when I want to be,” she said. “I get to be an electrical engineer when I want to be. I get to be a firmware engineer when I want to be.”

The failures she chases can be immense or microscopic. A rack-scale issue might involve high-speed signaling, thermal margins or power integrity. Another might come down to a screw tightened too far or the level of dust in a customer facility.

“The solution can be elusive,” Fiza said. “We have to follow the clues, ignore the red herrings and know where to look.”

When a log shows how something failed, Fiza’s job is to discover why. Validation engineers reproduce the issue, vary the conditions, investigate firmware, remove mechanical variables, probe signals, study scope shots and narrow the possible causes.

A single board may contain tens of thousands of components; a rack may approach half a million. Those parts must not merely coexist. They must behave as one system under stress, at scale, in the complex realities of production and deployment across diverse AI factory configurations.

“I wish people understood how complex the hardware is that AI needs to run on,” Fiza said.

For Fiza, the pressure of the work is inseparable from the pleasure of it. Bring-up, she said, is “like the Avengers assembling”: architects, designers, software engineers, firmware engineers, validation engineers, all in the room, racing toward a working system.

“One thing I know when I come to work is I’m never alone,” she said. 

To be a validation engineer is to practice a disciplined kind of suspicion: believe a system can work, then try to conceive of every way it might not. The job requires the doggedness of a great detective, as well as the diagnostic abilities of a general practitioner and the temperament of someone who meets catastrophic failure in the way others might a crossword.

Each project brings a new puzzle, a new failure mode and, in turn, a chance to make the next system better.

“With the products we have in the pipeline, I’m so excited,” Fiza said. “They’re going to change the world.”

NVIDIA Vera Rubin NVL72 Delivers Leading Performance in MLPerf Inference v6.1 Debut

First preview submission using NVIDIA Vera Rubin NVL72 systems delivers up to 3.7x better throughput than NVIDIA GB300 NVL72.
by

System performance, efficient infrastructure scaling and continuous software optimization are key levers that determine AI inference economics. Higher system performance means more tokens generated, resulting in higher revenue. Efficient scaling means throughput grows proportionally as hardware gets added, requiring fewer resources to serve users at scale. Continuous optimization means generating more value from infrastructure investments. 

Underlying all three is platform fungibility: the same infrastructure runs any model, any workload, from training to inference, recommender to reasoning, language to video, keeping utilization high.

The NVIDIA platform is purpose-built to optimize across all these, as highlighted by MLPerf Inference v6.1 results released today:

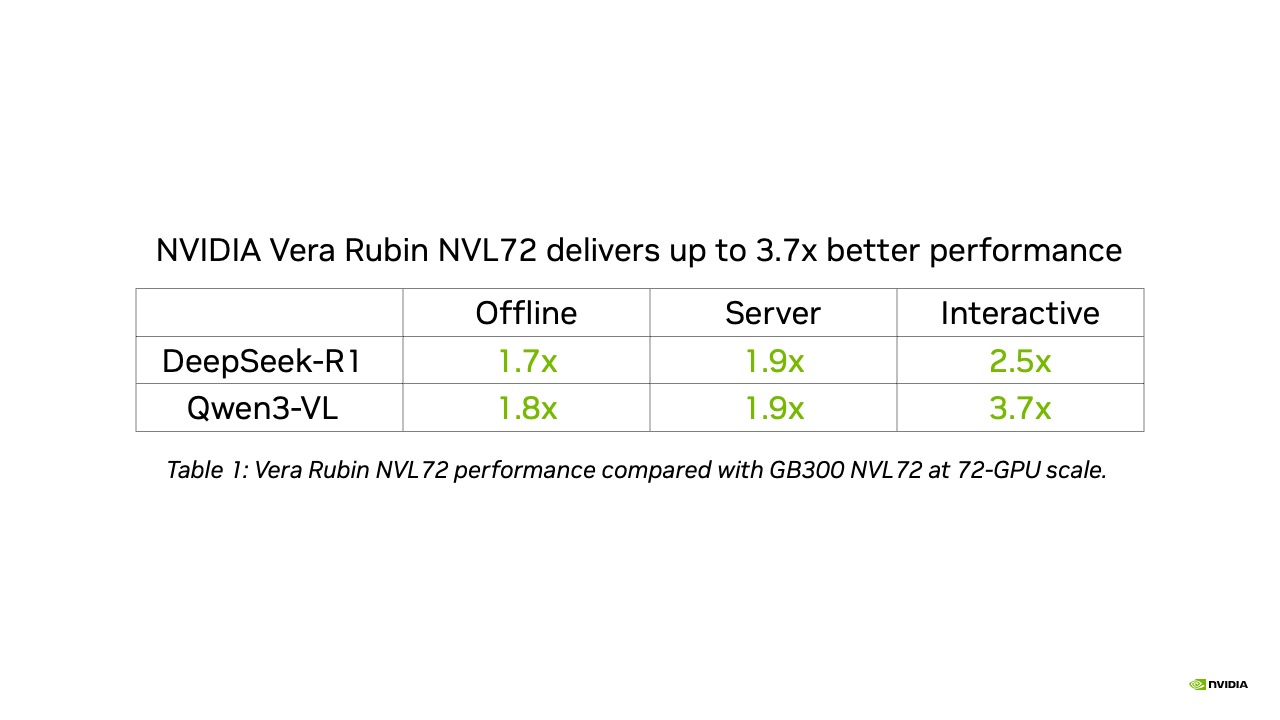
  • NVIDIA Vera Rubin NVL72 system debuts with leading performance: In its first MLPerf Inference preview submission, NVIDIA Vera Rubin NVL72 delivers up to 3.7x better throughput than GB300 NVL72.
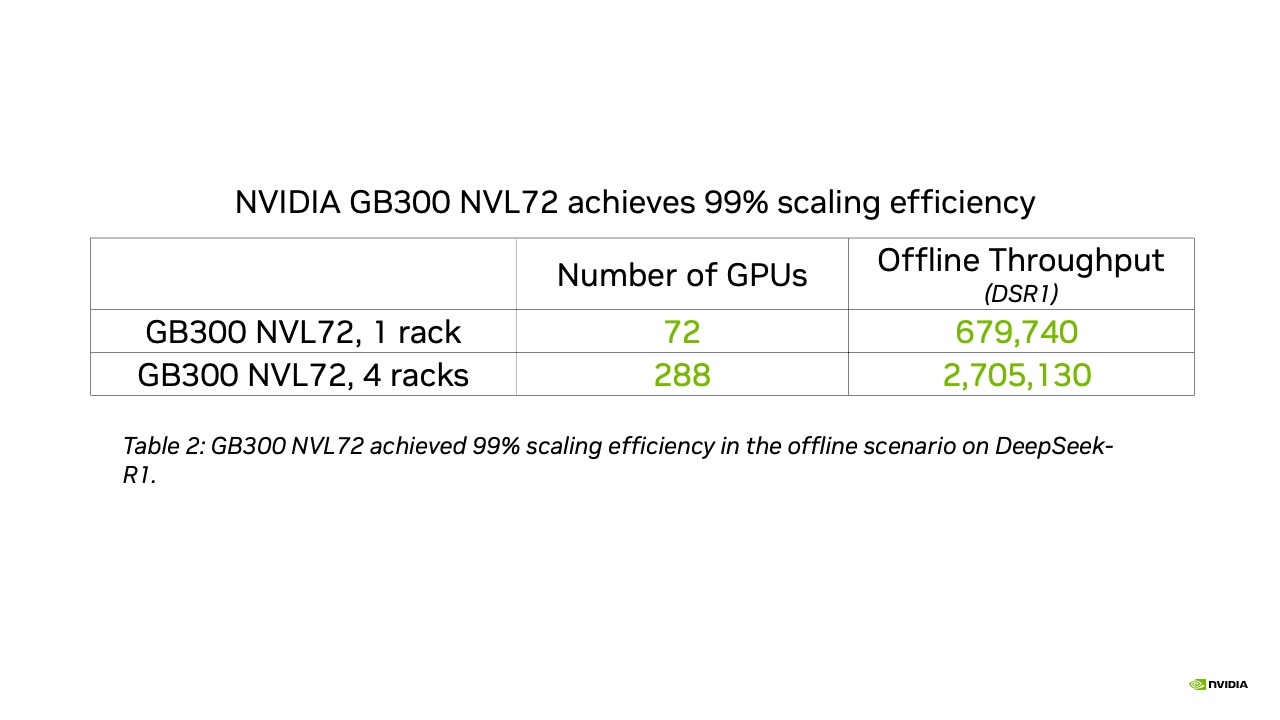
  • NVIDIA GB300 NVL72 scales with leading efficiency: A 288-GPU submission across four GB300 NVL72 racks achieved 99% scaling efficiency, with throughput growing nearly linearly from a single-rack baseline.
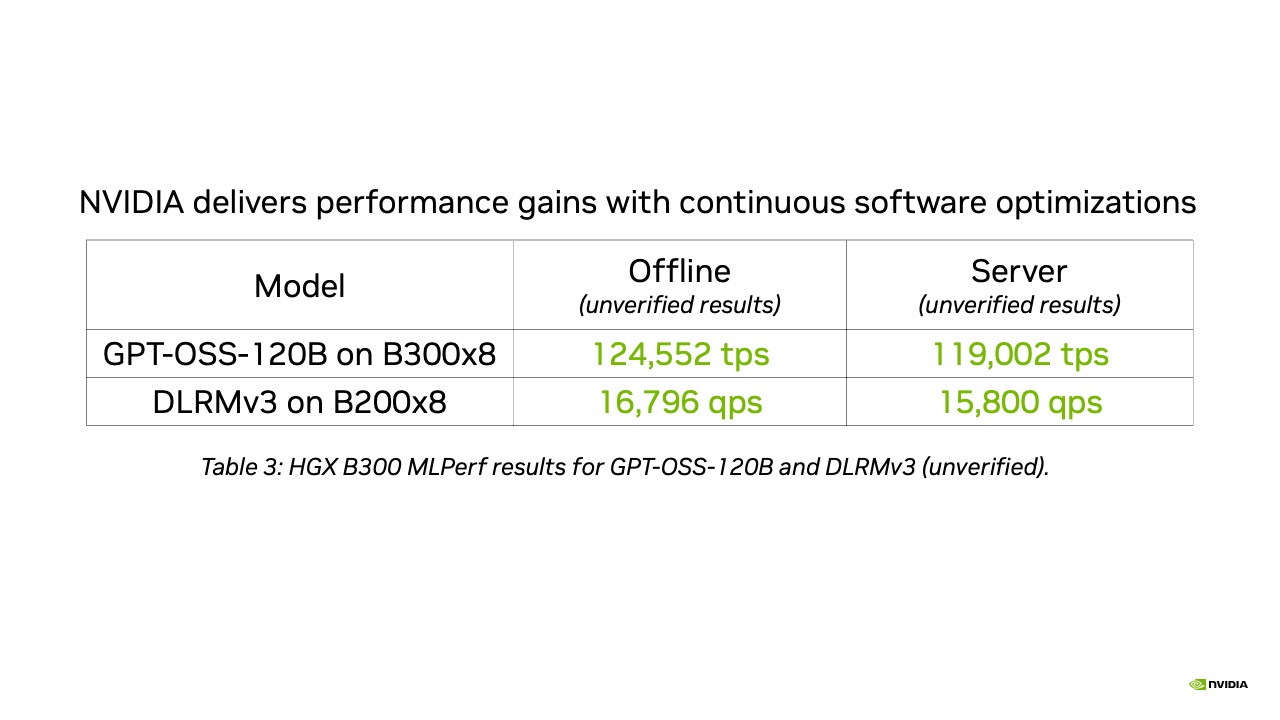
  • Continuous software optimizations drive performance gains: Software optimizations in NVIDIA’s MLPerf Inference v6.1 submissions delivered up to 1.6x higher performance over v6.0. Optimizations continued post-v6.1 submission, delivering further performance gains.

For organizations making AI infrastructure decisions, performance, scaling efficiency and software velocity are important considerations that determine long-term inference economics. 

Vera Rubin NVL72 Makes MLPerf Inference Debut With Leading Performance

NVIDIA submitted Vera Rubin NVL72 preview results on two of the most demanding benchmarks in the MLPerf Inference v6.1 suite: DeepSeek-R1 and Qwen3-VL. 

Vera Rubin NVL72 delivers up to 3.7x higher throughput than GB300 NVL72 on Qwen3-VL across offline, server and interactive scenarios, using vLLM with the NVIDIA Dynamo open source inference framework. On DeepSeek-R1, using the NVIDIA TensorRT-LLM library, throughput is up to 2.5x higher than GB300 NVL72. These early results showcase NVIDIA’s accelerated pace of innovation and how performance will improve with continuous software optimizations. 

MLPerf Inference v6.1, Closed Division. Results retrieved from www.mlcommons.org on Sep 16, 2026. NVIDIA platform results from the following entries: 6.1-0106 and 6.1-0074. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use is strictly prohibited. See www.mlcommons.org for more information.

This performance means each Vera Rubin NVL72 rack delivers significantly more tokens, serves more users and generates more revenue than a GB300 NVL72 rack, while lowering cost per token.

The results reflect full-stack codesign across hardware and software. Vera Rubin’s enhanced Tensor Cores and Transformer Engine accelerate both the prefill and decode stages of inference, while NVFP4 precision reduces memory footprint across model weights, attention and KV cache — increasing throughput with minimal loss of output quality. 

Vera Rubin submissions heavily used disaggregated serving, separating prefill and decode along with large-scale expert parallelism for maximum efficiency across the mixture-of-experts layers that power models like DeepSeek-R1 and Qwen3-VL. 

The NVL72 scale-up domain — powered by sixth-generation NVIDIA NVLink and NVLink Switch to deliver 10x higher packet rates and 3x lower latency than off-the-shelf Ethernet — provides the interconnect foundation that makes these techniques effective at rack scale. 

This codesign extends to NVIDIA’s partner ecosystem: Nebius also submitted Vera Rubin NVL72 preview results and demonstrated excellent performance.

AI agents, which reason, plan and act across multiple steps, are reshaping how inference performance is measured. In benchmarks designed to capture this shift, such as SemiAnalysis AgentX, Vera Rubin NVL72 delivered 30x better performance than GB300 NVL72 in preview testing. In addition, the upcoming MLPerf Endpoints benchmark will bring standardized measurement to agentic inference workloads, beyond what traditional throughput benchmarks capture.

NVIDIA GB300 NVL72 Scales With Leading Efficiency

Scaling efficiency — how effectively additional GPUs translate to throughput gains — is a key measure of AI infrastructure productivity. NVIDIA delivers this with high-bandwidth, low-latency scale-up interconnects within each rack, high-bandwidth networking between racks and efficient request orchestration across nodes.

NVIDIA’s DeepSeek-R1 (DSR1) submission scaled from a single GB300 NVL72 rack (72 GPUs) to four racks (288 GPUs), achieving 99% scaling efficiency in the offline scenario. Throughput grew nearly in proportion to the hardware added.

MLPerf Inference v6.1, Closed Division. Results retrieved from www.mlcommons.org on Sep 16, 2026. NVIDIA platform results from the following entries: 6.1-0073 and 6.1-0074. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use is strictly prohibited. See www.mlcommons.org for more information.

Scaling efficiency is key because more GPUs don’t automatically mean proportionally more throughput. If adding nearly double the GPU count delivered only a single-digit percentage improvement in throughput, the infrastructure cost would far outpace the performance return. The architecture, interconnect and software must all scale together.

GB300 NVL72 also demonstrated rack-scale efficiency on the WAN 2.2 text-to-video benchmark, reaching 0.65 720p videos per second at 5.7 seconds per video — 9x higher throughput and 7.5x lower latency than a single node.

Software Optimizations Drive Continuous Gains

NVIDIA platform undergoes continuous software development, delivering performance and feature improvements. 

In v6.1, GB300 NVL72 performance on Qwen3-VL improved up to 1.6x over v6.0 results. The gains came through lower KV cache precision, additional kernel fusion, better kernels and disaggregated serving with vLLM and NVIDIA Dynamo. 

Software optimization continued past the v6.1 submission deadline as well. Post-submission results, not yet verified by MLCommons, on GPT-OSS-120B and DLRMv3 show further performance gains. 

AI Inference at Every Scale

Beyond the NVIDIA Grace Blackwell and Vera Rubin NVL72 platform results, NVIDIA submitted Jetson AGX Thor results using NVIDIA TensorRT Edge-LLM on the newly introduced Edge-Agentic benchmark with Qwen3.6-27B.

The NVIDIA partner ecosystem participated broadly, with 19 partners — eight of them on multi-node Blackwell NVL72 systems — demonstrating excellent performance. This includes ASUS, Azure, Cisco, CoreWeave, Crusoe, Dell Technologies, Fujitsu, Giga Computing, HPE, Inventec, Lambda, MiTAC Computing, Nebius, Oracle Cloud Infrastructure, Quanta Cloud Technology, Red Hat, ScitiX, Supermicro and Wiwynn.

From compact edge devices to the largest AI factories, NVIDIA continues to advance performance across the full technology stack with an annual cadence of platform architectures, continuously improving software and an ecosystem built to deliver it at scale.

Learn more about the NVIDIA Vera Rubin platform.