country_code

Entos Transforms Drug Discovery and Design With NVIDIA AI-Powered Molecular Simulation

NVIDIA Clara Discovery is powering the San Diego startup’s new machine learning approach for developing next-generation therapeutics.
by
molecular simulation

More knowledge means more informed predictions. That’s the principle San Diego-based startup Entos is applying to revolutionize drug design with an AI-powered approach that enables a thousandfold acceleration in molecular properties prediction.

Drug discovery is a notoriously time-consuming and data-intensive process, but Entos’ OrbNet architecture changes that. It requires 30x less data to train a model for molecular drug discovery with quantum accuracy and 100x fewer experiments to find promising drug compounds — cutting through the waiting time and complexities associated with traditional therapeutic drug discovery methods.

The company, a member of the NVIDIA Inception program for startups revolutionizing industries with advancements in AI, data science and high performance computing, is advancing its work with NVIDIA Clara Discovery — a collection of state-of-the-art frameworks, applications and pretrained models built to unlock insights about how billions of potential drug molecules interact inside our bodies.

“Our physics-based approach means we include more qualities about the underlying quantum mechanics into the machine learning model,” said Tom Miller, CEO of Entos. “This enables us to make better predictions, even while using less data.”

Entos is focusing on identifying drug molecules that could deactivate proteins linked to certain forms of cancer. By including quantum mechanics calculations into its machine learning workflow, the startup can more quickly narrow the pool of potential compounds that bind with these target proteins.

Bringing AI Into the Drug Discovery Process

Machine learning is transforming the way scientists approach everything from climate science to drug discovery. Now the combination of AI and machine learning is leading to a new way of doing science, creating a hybrid of deep learning and physics-based simulation to transform the way drugs are discovered.

Drug discovery is a data-intensive process where researchers perform computationally dense calculations to simulate how molecules and proteins interact to identify the right therapeutics. Traditionally, these forms of quantum calculations are extremely expensive to perform and take weeks or months to complete.

These computational experiments benefit from the incorporation of AI and accelerated computing by allowing researchers to simulate the interaction of a drug with a protein at quantum accuracy. The simulations are far too computationally expensive to perform using traditional quantum mechanical calculations.

Entos optimizes its OrbNet drug discovery software on NVIDIA DGX A100 Tensor Core GPUs. The OrbNet AI model — developed jointly at Caltech by Entos CEO Tom Miller and Anima Anandkumar, director of machine learning research at NVIDIA — enables robotic synthesis and high-throughput experimentation to speed up therapeutic design.

“OrbNet uses a graph neural network built on domain-specific features that account for interactions between atoms. Further, we account for symmetries such as three-dimensional rotations,” said Anandkumar. “These design considerations make it possible to train OrbNet only on small molecules — those with less than 40 atoms — and directly apply the model on large protein molecules with a high degree of accuracy.”

By collaborating with NVIDIA experts, Miller’s team of scientists is able to perform high-throughput experimentation and “open new doors to what we can go after,” he said.

Unlocking the Potential of Covalent Bonds

Recent developments in machine learning are transforming the size and scale of chemical databases that researchers can trawl for promising drug compounds. AI models also allow scientists to study the innumerable chemical reactions of enzymes within the body in a new way.

Together, these advancements are enabling the study of entirely new classes of drugs that researchers were unable to investigate with previous methods.

One promising technique involves the creation of drug molecules that form covalent bonds with the target protein. If therapeutics can form these bonds with only the target protein, patients could be prescribed smaller doses and experience fewer side effects. Entos researchers plan to apply this method to disease areas including cancer, diabetes and cystic fibrosis.

Entos has forged partnerships with leaders in the pharmaceuticals, materials and chemical industries and raised $53 million in July to support its efforts to create meaningful therapies with high accuracy. The company credits active collaborations with the NVIDIA healthcare team as an asset in getting connected to technical resources and assistance in optimizing its applications on NVIDIA hardware architecture.

Hear from Entos and additional Inception startups at NVIDIA GTC, running online through Nov. 11. Tune in to a healthcare special address by Kimberly Powell, NVIDIA’s VP of healthcare.

Watch NVIDIA founder and CEO Jensen Huang’s GTC keynote address below. Subscribe to NVIDIA healthcare news.
Delivering Vera: NVIDIA’s First CPU Built for Agents Is Shipping Now

NVIDIA Vice President of Hyperscale and HPC Ian Buck hand-delivers Vera CPU systems across the AI ecosystem as Vera begins shipping at scale.
by

NVIDIA NVLink Fusion Expands With NVHBM Custom High-Bandwidth Memory

Amazon’s Annapurna Labs will be the first to collaborate on NVHBM technology alongside NVLink Fusion.
by

The next wave of AI is placing new demands on infrastructure. 

As AI agents and trillion-parameter workloads become mainstream, the performance of AI infrastructure depends not only on compute, but on how compute, memory, storage, networking and software are designed together as a unified system.

To help hyperscalers and AI innovators build the next generation of semi-custom AI infrastructure, NVIDIA today expanded NVIDIA NVLink Fusion with NVIDIA NVHBM, a next-generation high-bandwidth memory technology that brings higher memory performance and efficiency to XPUs. It will be validated and offered by leading memory partners, extending this advanced memory capability to NVLink Fusion customers.

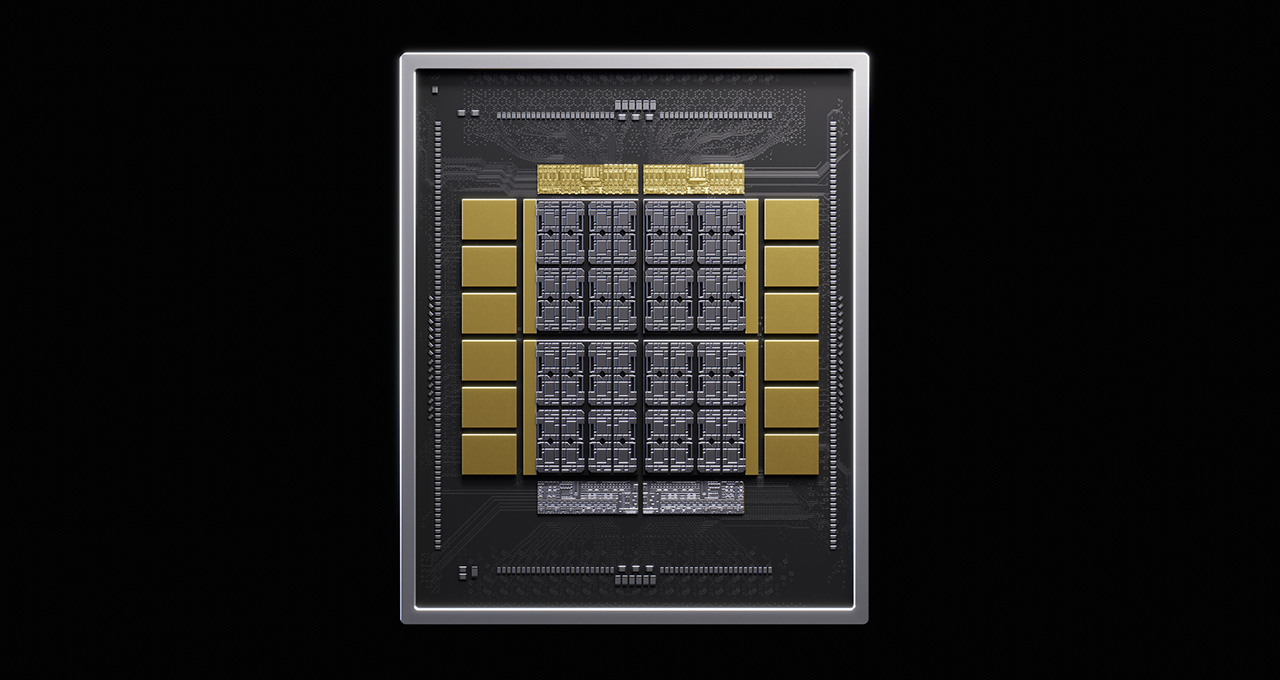
Traditional HBM architectures place the memory controller on the XPU die, consuming valuable silicon area that could otherwise be dedicated to compute. NVHBM, built on the same technology that NVIDIA will use for future GPUs, integrates NVIDIA’s custom memory controller into the HBM base die. 

By integrating the memory controller into the 3D HBM stack instead of the XPU, NVHBM delivers up to 30% greater memory bandwidth and 15% lower HBM power consumption, and frees up to 25% more area on XPU compute die compared with standard HBM4E.

NVIDIA is establishing a standard NVHBM implementation, available from multiple memory providers. This reduces the engineering effort required to integrate and qualify memory across multiple suppliers — giving NVLink Fusion customers a faster path for bringing custom AI chips to market. 

Amazon’s Annapurna Labs will be the first to work on NVHBM as part of its broader collaboration with NVIDIA around NVLink Fusion.

AWS and NVIDIA Continue NVLink Fusion Collaboration

Amazon’s Annapurna Labs will work with NVIDIA on NVHBM technology and the NVLink scale-up architecture to enhance performance and efficiency for AI workloads.

This builds on AWS’s previously announced support for NVLink Fusion. Annapurna Labs will support NVLink Fusion with its next-generation Trainium chips starting with Trainium4, which would allow Amazon chips and NVIDIA GPUs to work together with common rack-scale architecture.

“NVHBM represents a new architectural approach to advancing high-bandwidth memory performance and efficiency,” said Nafea Bshara, vice president of Annapurna Labs at Amazon. “We look forward to this technology collaboration to benefit future AWS infrastructure designs.” 

Vertically Integrated and Horizontally Open

NVLink Fusion enables partners to connect custom XPUs and CPUs to NVIDIA’s rack-scale platform.

Partners can access NVIDIA NVLink chiplets, NVLink-C2C, NVLink Switches and NVIDIA MGX systems and racks, as well as a broad ecosystem of CPU partners, ASIC designers, system manufacturers and technology providers. 

Offered with each generation of NVIDIA’s rack-scale system architecture, NVLink Fusion allows hyperscalers and AI-native companies to focus engineering resources on XPU innovation while using a proven technology stack for scale-up and scale-out networking, rack-scale systems and software — creating a faster, lower-risk path to deploying semi-custom AI infrastructure.

Learn more about NVLink and NVLink Fusion.

How XPUs Meet a World-Class AI Factory

Deploying custom silicon with leading AI infrastructure enables hyperscalers and AI-native companies to build flexible AI factories that combine specialization with scale.
by

To generate intelligence at scale, AI factories run continuously, and their economics are defined by delivered output: tokens per second, tokens per watt, cost per token, utilization and uptime. 

That requires AI infrastructure designed and built as a full factory, not a collection of individual accelerators.

Hyperscalers and AI-native companies building custom XPUs must consider not just XPU design, but the design and development of the entire AI platform, including scale-up and scale-out networking, rack-scale architecture, production factory software and a robust supplier ecosystem. 

At AI factory scale, this path is complex and costly, and represents a fundamental obstacle to getting XPUs to market quickly. 

Breaking the constraint means combining custom XPUs with proven, mature infrastructure — allowing builders to focus innovation where it matters most while harnessing established technology for the rest. 

NVLink Fusion delivers on that need, connecting XPUs to NVIDIA’s world-leading AI infrastructure to increase performance, accelerate time to market and mitigate risk for semi-custom AI factories.

Unlock XPU Performance With Fast Scale-Up

For modern workloads such as running trillion-parameter models, mixture-of-experts architectures and agentic AI, if the scale-up fabric cannot keep up, utilization drops and cost per token rises.

A scale-up networking solution must excel on three dimensions: 

  • Delivered performance: End-to-end network performance, in-network compute and  mature software integration.
  • Factory resiliency: Uptime, continuous health monitoring and telemetry, and component-level serviceability while the factory keeps running.
  • Platform maturity: Reduced operational risk by using a mature technology stack with a demonstrated track record of large-scale deployments and realized return on investment. 

As an example, NVLink Fusion brings XPUs into the NVIDIA NVLink scale-up domain. Sixth-generation NVLink provides leading high-bandwidth, low-latency networking across a 72-XPU domain. The end-to-end latency for XPU-to-XPU transfers is 3x lower than alternative solutions based on off-the-shelf Ethernet, and the packet rate is 10x higher.

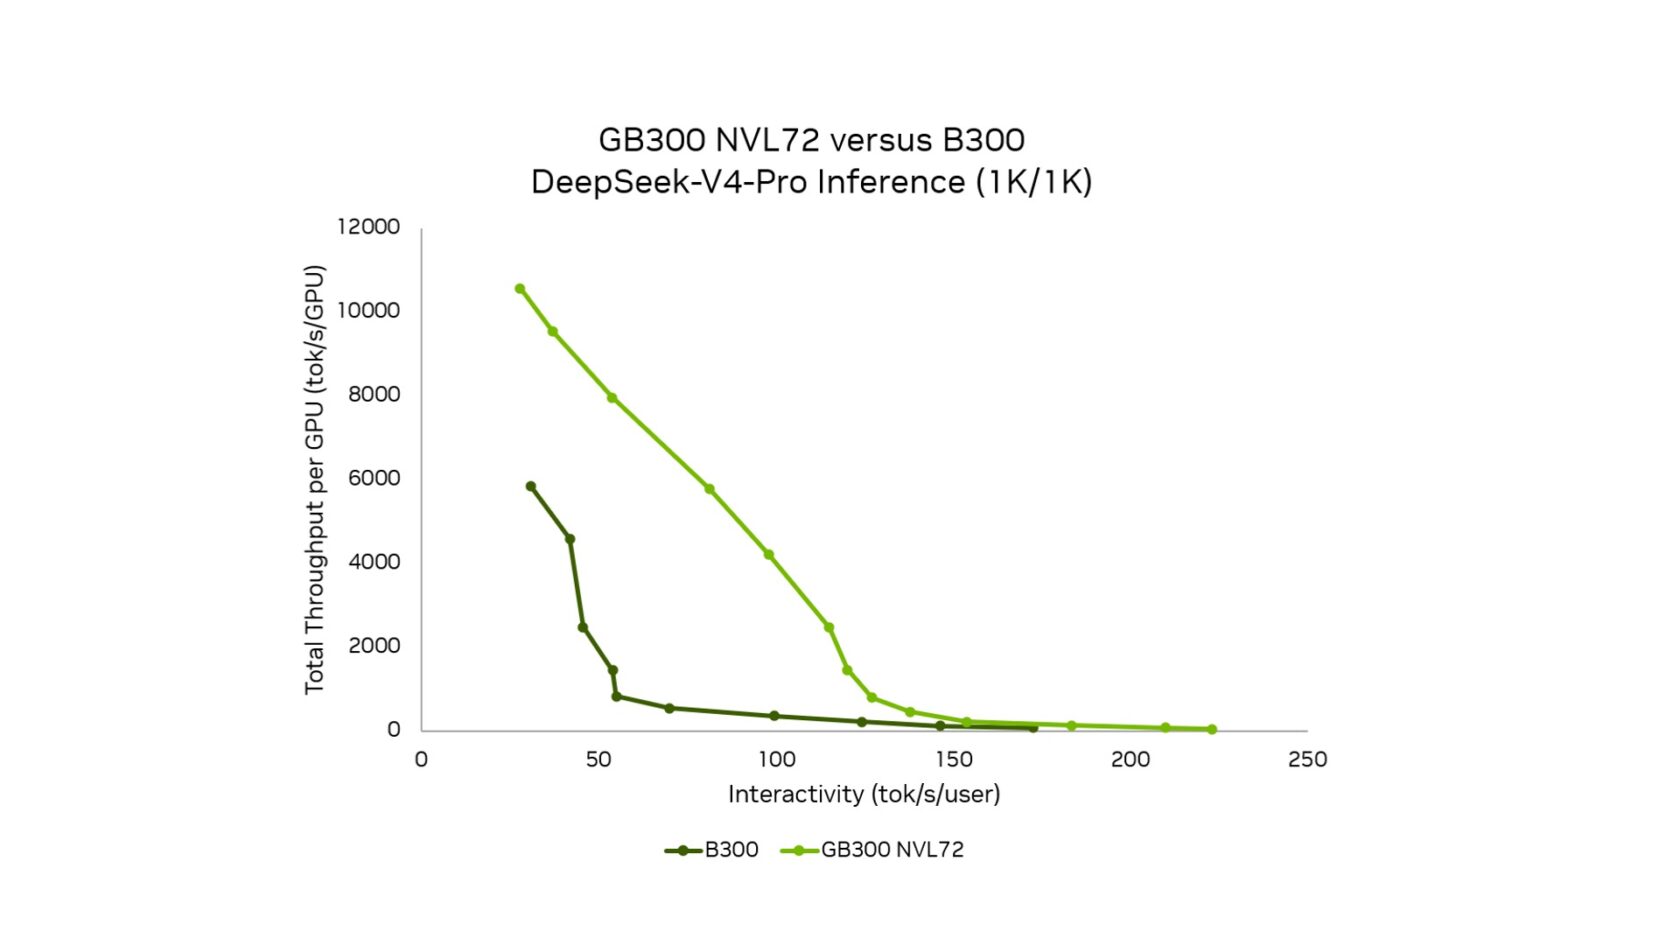
For end-to-end performance, NVIDIA GB300 NVL72 systems help deliver significantly higher throughput and better interactivity compared with configurations that don’t use NVL72, and future NVLink roadmap configurations include domains of up to 1,152 accelerators and co-packaged optics.

A Pareto chart comparing GB300 NVL72 with B300 inference throughput performance in tokens per second per GPU on DeepSeek-V4-Pro at ISL=1K and OSL=1K sampled at various interactivity points in tokens per second per user. GB300 NVL72 is more than 10x the throughput of B300 in the middle of the Pareto between 70 and 100 tokens per second per user.
The 72-GPU NVLink scale-up domain enables GB300 NVL72 to deliver higher per-GPU throughput and interactivity compared with NVIDIA B300. Results from NVIDIA’s AI Inference Performance Benchmarks page.

NVLink Fusion also includes NVIDIA NVLink-C2C for connecting XPUs to NVIDIA Vera CPUs or other ecosystem CPUs, delivering up to 6x the energy efficiency of a PCIe interface — helping remove barriers between control and compute for agentic systems.

A Proven Stack and Ecosystem for Development and Deployment

Teams developing custom XPUs often underestimate the effort and complexity of turning XPU innovation into data center deployment. This includes:

  • Integrating high-speed CPU and scale-up interfaces
  • Sourcing and validating a scale-up network solution
  • Designing compute and switch trays
  • Designing and validating a rack architecture, including cooling and power
  • Integrating security and storage
  • Managing a complex supplier ecosystem

The ideal platform provides all of this, allowing teams to focus on targeted innovation while using proven solutions for the rest.

NVLink Fusion is supported by an ecosystem designed for rapid development, integration and deployment, spanning ASIC design, CPU, and IP and optical interconnect partners.

“NVLink Fusion gives customers the ability to choose the CPU architecture, the performance level, the software capabilities that best meet their needs for the workloads that they care about,” said Tim Wilson, vice president and general manager of data center silicon engineering at Intel.

NVLink Fusion adopters can also use the NVIDIA MGX rack-scale architecture and the same supply chain used for MGX-based systems such as NVIDIA Vera Rubin NVL72. Manufacturing partners manage design and integration, while MGX suppliers provide the building blocks for rack, cooling, power and emerging 800 VDC designs.

“With Vera Rubin [NVL72], we are looking at almost 100% automation of system builds in the manufacturing line,” said Jack Luoh, head of product and solution at QCT and Quanta Computer. “Most of those investments can be leveraged if the XPU leverages NVLink Fusion.”

The NVIDIA AI infrastructure platform is vertically integrated and horizontally open. NVLink Fusion adopters can optionally incorporate NVIDIA Rubin GPUs, Vera CPUs, co-packaged optics switches, ConnectX SuperNICs, BlueField DPUs, Mission Control software and full-rack solutions including NVIDIA Vera Rubin NVL72, Vera CPU Rack, LPX, STX and SPX.

Managing Risk With Infrastructure Standardization

AI factory planning doesn’t wait for silicon. Power procurement, facility design, cooling, rack layout and network architecture begin long before the final accelerator mix is available. A data center locked to one chip can become a schedule risk.

Different workloads may favor different accelerators, including XPUs, GPUs, CPUs and LPUs. GPU systems may work alongside semi-custom systems for training, post-training, reasoning, retrieval and serving.

“The value of the NVLink Fusion program is … [customers] can deploy their rack-level solution with the NVIDIA GPU, and then they can decouple the development of their XPU and put it at a different pace,” said Vince Hu, corporate senior vice president and general manager of the data center and computing business group at MediaTek.

NVLink Fusion addresses these challenges  through a unified architecture. XPU- and GPU-based systems such as Vera Rubin NVL72 can share rack footprints, networking, cooling, power delivery and management systems. Operators can move forward with buildout while deferring the precise silicon mix, then reprovision capacity as workload demand, silicon supply and business priorities change. 

“NVLink Fusion allows the hyperscalers or the custom ASIC designers to integrate their own custom CPU or XPU and bridges the NVIDIA technology with a third-party process to create a unified rack-scale architecture,” said Lie-Szu Juang, chair and chief strategy officer at GUC.

Designed, Validated and Operated as a Factory

Factory buildout is expensive, and mistakes can require costly rework. Infrastructure must be validated before construction begins. NVLink Fusion aligns with the NVIDIA DSX reference architecture for AI factories: codesigning buildings, power, cooling, compute and networking. The NVIDIA Omniverse DSX AI Factory Blueprint provides a digital twin and open reference design for gigawatt-scale AI factories, enabling partners to model facilities and technology together before deployment.

At the rack level, serviceability is part of performance. Reference compute trays feature 100% liquid cooling with no fans, cables or hoses, and allow trays to be removed while the rest of the rack remains operational. NVLink Switch trays are also liquid cooled and support continued operation during service.

“With NVLink Fusion we can use proven NVL72 rack design to have time-to-market, and we can have access to multiple suppliers to help us to deliver more into the hands of our customers,” said CC Lee, senior hardware development manager at Annapurna Labs, an Amazon company.

Software completes the factory. NVIDIA NCCL for distributed workloads, NVIDIA Dynamo and NIXL for disaggregation and NVIDIA Mission Control for cluster management, telemetry and debugging help operators run mixed AI infrastructure as a coordinated system.

With NVLink Fusion, XPUs can now meet a world-class AI platform, enabling hyperscalers and AI-native companies to build unified, semi-custom AI factories that combine the strengths of many builders into infrastructure no one company could build alone.

Learn more about NVLink Fusion.