country_code

How AI Is Changing Medicine

by
How AI Is Changing Medicine

Doctors and nurses stand at the front lines of our healthcare system, providing immediate care. But there’s an equally important universe of researchers working in parallel who are advancing the tools and knowledge clinicians can draw on to treat their patients.

These researchers are developing new drugs to solve as-yet incurable diseases, simulating biological organisms and structures to better understand how they work, and diving into genomic data to find genetic markers related to specific health conditions.

And, for an ever-growing number of applications, they’re doing so using AI and accelerated computing.

How AI Is Changing Drug Discovery

There are almost as many potential drug-like molecules as there are atoms in the observable universe. Pharmaceutical companies and researchers pour years of effort and billions of dollars into exploring this vast library of molecules to discover new treatments for diseases.

Scientists use their expertise to guess which drug molecules will be able to stop a particular ailment in its tracks. They traditionally focus on one disease at a time, performing research over many years. With AI, they can instead virtually model millions of molecules and screen hundreds of diseases at a time.

Deep learning can pick up on the biochemical laws that govern how a drug molecule will act in the body, helping researchers understand the potential side effects of a drug molecule — or even come up with new, synthetic molecules that could treat a disease.

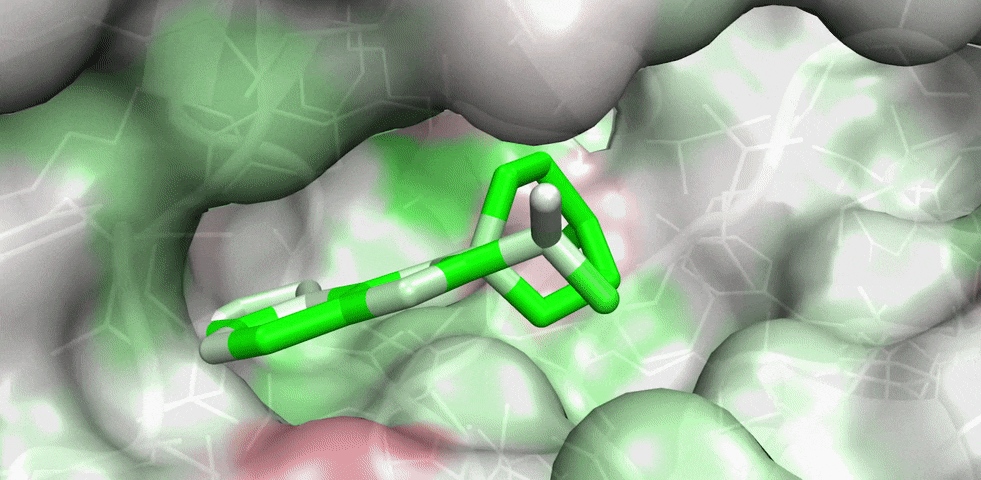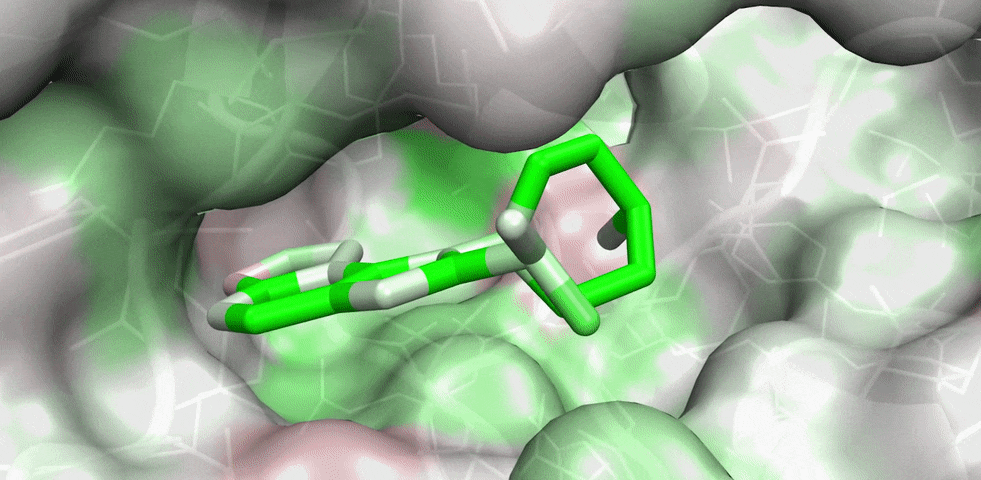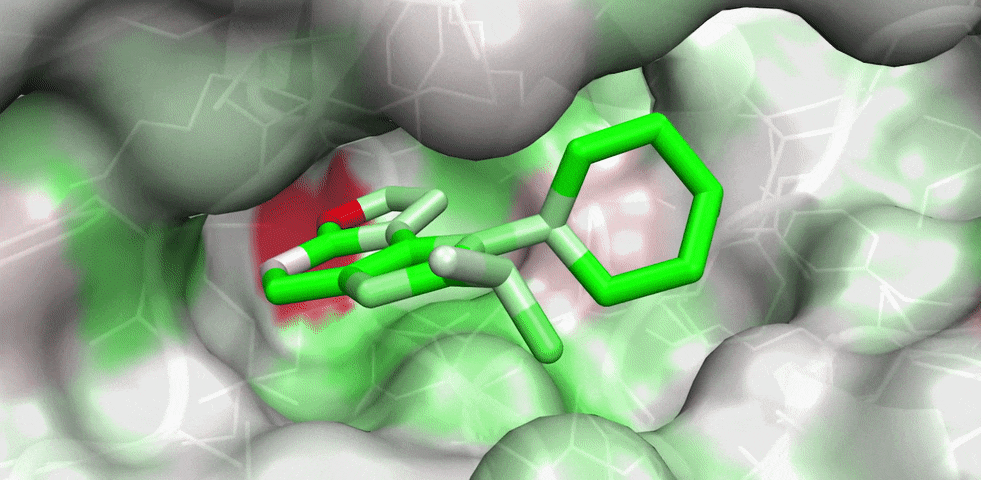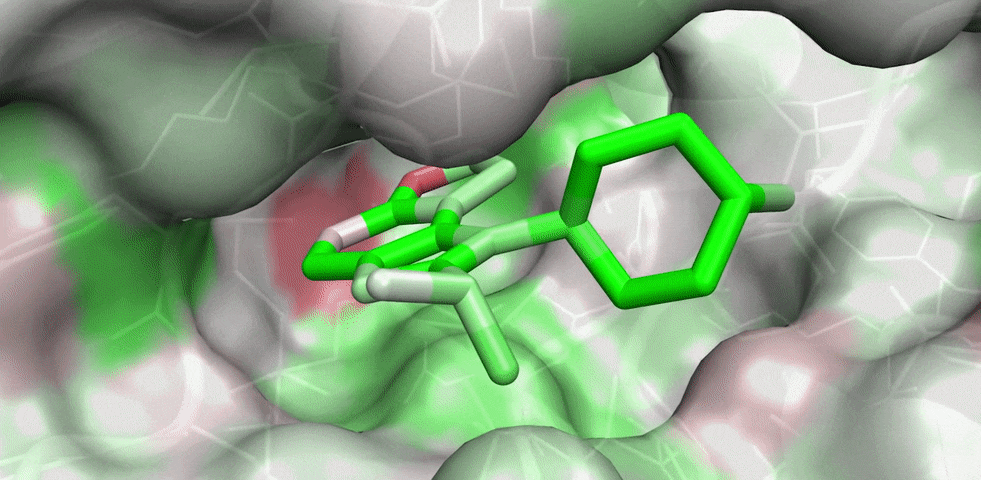
University of Pittsburgh researcher David Koes is doing just that, using NVIDIA GPUs for molecular docking, the process of simulating how a drug candidate will bind to a target protein. His team developed a deep learning model that improved their prediction accuracy from 52 percent to 70 percent.

And Recursion Pharmaceuticals, a member of the NVIDIA Inception program, is using more than 100 GPUs to train its neural networks for drug discovery across several therapeutic areas, including hundreds of rare diseases that currently lack treatments.

Recursion’s deep learning models analyze microscopy images, determining whether a drug compound is effective at healing diseased cells. Using AI allows the company to screen hundreds of features from more than 10 million cells in a week.

How AI Is Changing Genomics

Another area of medicine where the size and complexity of data are staggering is genomics. Despite being a relatively young field, genomics is growing fast, with datasets doubling in size around every eight months.

Around a million whole human genomes have been sequenced worldwide, giving scientists an ocean of granular data that can be harnessed for precision medicine, immunotherapy and population studies. But once this data is collected, it’s computationally demanding to analyze.

Scripps Research Translational Institute is partnering with NVIDIA to build deep learning applications for more affordable genome sequencing and better mutation detection from genomic data. Startups, too, are harnessing GPUs to solve challenges in genomic analysis.

Just as GPUs solve graphics problems by processing many pixels independently, they can break genetic information into tiny, individual pieces that can be crunched separately and then strung back together, says Ankit Sethia, cofounder of Inception startup Parabricks.

The company is using an NVIDIA DGX-1 server to detect key markers and outliers in a sequenced genome — shrinking the time it takes from a couple days to under an hour.

How AI Is Changing Medical Research

Researchers in universities around the world are using AI and GPUs to simulate biological structures and diseases that we don’t yet fully understand.

In Australia, a team at Monash University is using a process called cryo-electron microscopy to develop high-resolution 3D models of molecules, a compute-intensive process that requires an NVIDIA GPU-powered supercomputer to run.

The researchers are using the technology to develop drugs that can combat superbugs, or drug-resistant bacteria.

In the U.S., Colorado State University researchers are simulating an enzyme found in the deadly dengue virus, which infects hundreds of millions of people each year. Using GPU-powered supercomputers at the San Diego Supercomputing Center, the team was able to discover new aspects of enzyme motion.

With increased precision, this work could lead to insights that stop diseases like dengue from spreading.

Deep learning can also be used to help researchers amass the source data they need to develop breakthrough healthcare applications. At NVIDIA, researchers are using generative adversarial networks, or GANs, to advance medical research by generating abnormal brain MRIs to train neural networks for medical imaging.

These synthetic MRIs can help solve a challenge developers in the medical community often face: a lack of balanced, reliable training data to train their deep learning models.

See the NVIDIA healthcare page for more.

Lambda Boosts AI Factory Resiliency and Efficiency With NVIDIA Photonics

by

To train an AI model, thousands of GPUs have to work together, requiring a network that’s fast, efficient and resilient.

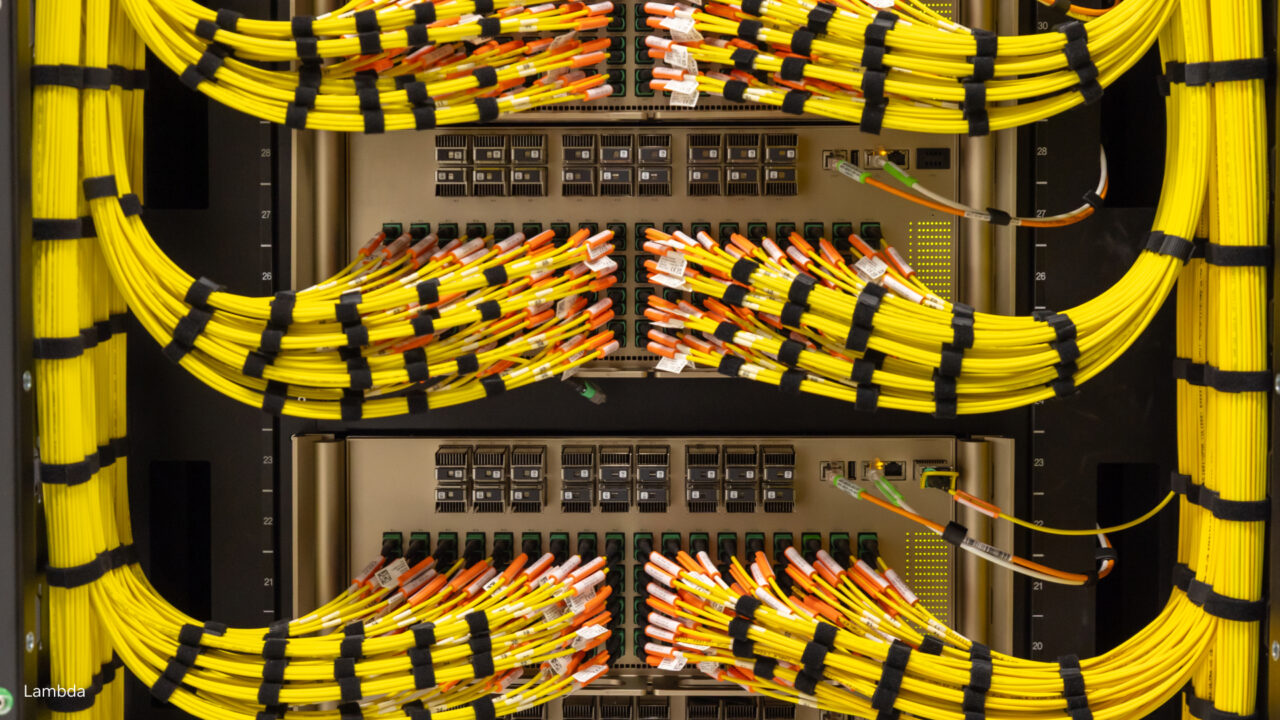
Lambda is tackling the network piece of the puzzle with NVIDIA Photonics co-packaged optics (CPO) switches. The cloud provider is using the switches to connect NVIDIA GB300 NVL72 racks with more than 10,000 GPUs, delivering lower power, higher resiliency and longer mean time between interruptions (MTBI) to an AI factory at scale.

“Networking has to keep pace with the demands of increasingly large AI clusters,” said Dave Ward, president of cloud services at Lambda. “Bringing co-packaged optics into a deployment of this scale is an important step toward building the infrastructure needed to support the next generation of AI.” 


In the company’s tests using the switches, network latency — the time needed for moving data — dropped by about 4% at rack scale and by up to about 10% at pod scale. Across rack, scalable unit and pod configurations, the network maintains the same throughput as conventional pluggable optics.

Delivering Power Efficiency and Resiliency at Scale

Improving power efficiency and resiliency matters because the network sits at the center of AI factory productivity. 

In a large training job, one interrupted link can stall thousands of GPUs. With agentic inference, one network disruption can introduce cascading latency effects on many agents. Every interruption costs time, and every watt spent on networking is a watt not available for compute. 

NVIDIA Photonics addresses both power efficiency and resiliency. By replacing pluggable transceivers with co-packaged optical engines on the switch package, it delivers up to 5x better power efficiency and up to 15x higher reliability than conventional pluggable optics. It also uses 4x fewer lasers, which means fewer components that can fail.

Cooler Optics, Replaceable Light Sources Increase Resiliency

Lambda’s deployment uses NVIDIA Photonics switches, each with 144 ports running at 800Gb/s. Liquid cooling carries heat away from the switch chip and optical engines. 

The company reports a median optics temperature of 36°C, compared with 51°C for conventional pluggable optics, and its tests find more stable signal integrity.

NVIDIA Photonics also brings the electrical-to-optical conversion closer to the switch chip. Each switch has 18 removable external light sources, which supply light to the optical engines. Optical engines sit alongside the chip on the same package and convert electrical signals into light that carries data over fiber between parts of the cluster. 

Technicians can replace the light-source modules in the field, unlike traditional pluggable optics, which require replacing the entire module if a laser fails.

Co-packaging shortens the electrical path from inches to millimeters, which reduces signal loss. It also removes the need for retimer chips, cutting both power draw and the number of parts in the signal path.

Explore NVIDIA Photonics and read Lambda’s deployment announcement.


Building Trusted AI Infrastructure for Safe and Secure AI

NVIDIA and cybersecurity partner Eclypsium are advancing infrastructure security for cloud computing and agentic AI with NVIDIA BlueField and Eclypsium infrastructure assurance.
by

AI is transforming how organizations build applications, process information and automate decisions. As AI agents become increasingly autonomous, access sensitive data, interact with tools and take actions across enterprise systems, securing the infrastructure that powers them becomes more important than ever.

AI security extends beyond models and applications. It encompasses the compute, networking, storage, firmware and management systems that execute workloads and enforce security controls.

Trusted AI must therefore be anchored in trusted infrastructure. That means moving from assumed trust to verifiable trust: evidence that critical infrastructure is in a known-good state, remains correctly configured and has not drifted because of vulnerabilities, unauthorized modifications, supply-chain compromise or persistent threats.

NVIDIA and cybersecurity partner Eclypsium are advancing infrastructure security for cloud computing and agentic AI

NVIDIA’s built-in platform protections and Eclypsium’s infrastructure provide the trust layer for building and maintaining trust in the infrastructure powering AI. The result is a stronger chain of trust, from verified hardware and firmware to independently enforced AI agent execution.

NVIDIA BlueField DPUs provide a foundation for securing this infrastructure, combining programmable acceleration with hardware-rooted trust, isolation and configurable security boundaries. Every cloud provider builds their infrastructure around DPUs. These capabilities help cloud providers and enterprises build secure, scalable infrastructure tailored to their operational requirements.

A growing cybersecurity ecosystem extends this foundation with additional capabilities. Eclypsium brings expertise in continuous infrastructure security, firmware integrity assessment, configuration analysis and monitoring, helping organizations strengthen visibility and operational assurance across their environments.

Security by Design With NVIDIA BlueField 

Modern cloud and AI infrastructure relies on specialized processors that accelerate networking, storage, security and management.

NVIDIA BlueField DPUs combine high-performance networking, programmable computing and in-silicon acceleration to run critical infrastructure services independently of host workloads.

This separation establishes distinct trust domains, allowing infrastructure operators to manage and protect underlying resources independently of the applications and operating systems running on their servers.

BlueField runs NVIDIA Sentry, part of the NVIDIA OpenShell Reference Architecture. This role in protecting autonomous AI agents makes securing the DPU increasingly important. BlueField has dedicated Arm CPU cores, an operating system, firmware and a management controller, and it moves data directly into host and GPU memory as part of its normal function. That privileged position makes BlueField an effective independent control point, and is why the DPU belongs in every operator’s security model, asset inventory and monitoring.

BlueField is engineered with defense in depth, beginning with a hardware root of trust and extending across firmware, operating systems, software and device management.

Its security architecture incorporates authenticated boot, hardware-enforced isolation, protected key management, secure firmware updates, rollback protection and device attestation. These mechanisms work together to protect platform integrity and enforce security boundaries.

Security also extends throughout the product lifecycle. NVIDIA follows rigorous secure development practices, including threat modeling, architecture and code reviews, automated security analysis, vulnerability management, fuzzing and offensive security research.

No complex computing platform is immune to vulnerabilities. That’s why NVIDIA maintains a continuous commitment to security engineering, vulnerability response and software and firmware updates throughout the supported product lifecycle.

Configurable Security for Different Infrastructure Trust Models

No two infrastructure environments have identical security requirements.

A hyperscale cloud supporting multiple tenants operates under different trust assumptions than a single-tenant enterprise AI cluster or an air-gapped AI environment.

These differences influence how administrative privileges, management interfaces, device access and isolation boundaries should be configured.

A defining advantage of DPUs is their combination of in-silicon acceleration and programmable computing. Unlike conventional high-speed network adapters, DPUs provide dedicated compute resources capable of running sophisticated infrastructure services and policies independently of the host.

NVIDIA BlueField uses this programmability to support different deployment models through configurable security boundaries. Operators can determine which capabilities to enable, how interfaces are exposed and how infrastructure access is controlled.

For example, a cloud provider can place tenant workloads and the host operating system in one trust domain while operating infrastructure services in a separate domain controlled by the provider.

BlueField supports configurations that can be locked into cryptographically attestable trust profiles, helping operators establish and verify intended security boundaries.

The presence of a capability or interface does not mean every deployment must expose or enable it. Secure infrastructure design requires defining the appropriate trust model and configuring the platform accordingly.     

Memory-access protections are an important example. DPUs, GPUs and management controllers can read and write system memory directly through direct memory access. Eclypsium’s research demonstrates the importance of host controls such as IOMMU translation, PCIe access control services and address translation services. Eclypsium enables operators to verify the configuration of critical hardware settings rather than assume it. 

This flexibility enables organizations to balance security, performance and operational requirements without imposing a one-size-fits-all architecture.

Extending Infrastructure Security Through the Ecosystem

Security capabilities built into infrastructure provide the foundation for protection. Cybersecurity partners can build on that foundation to address additional operational requirements.

Eclypsium brings complementary capabilities focused on infrastructure visibility, firmware integrity, configuration assessment and ongoing monitoring. Eclypsium AI Infrastructure Assurance verifies hardware and firmware against known-good baselines, identifies vulnerabilities and insecure configurations, monitors device and firmware posture, and detects drift, unauthorized modifications and persistent threats below the operating system.

For organizations seeking visibility across their environments, Eclypsium’s technologies can help identify infrastructure components, assess firmware, and detect threats, malware, vulnerabilities and configuration risks, as well as changes that may affect their security posture.

These capabilities give operators additional tools to evaluate and manage infrastructure security. Together, these capabilities independently check hardware integrity and establish trust in the underlying infrastructure based on verifiable evidence.

For example, an organization can establish an approved infrastructure configuration during deployment, use BlueField’s built-in security mechanisms to protect platform integrity and use Eclypsium’s assessment capabilities to identify unexpected configuration changes or emerging firmware risks.

The value extends beyond any single device. Modern AI infrastructure includes GPUs, DPUs, management controllers, networking equipment and other components, each contributing to the overall security posture.

Eclypsium’s broader infrastructure assessment capabilities can help organizations maintain visibility across these components as environments grow and evolve.

No single security control can establish trust across the entire AI stack. Defense in depth requires platform security, independent verification and continuous assurance working together, each providing evidence that the other layers are operating on a trusted foundation. BlueField provides security by design, while Eclypsium provides additional verification and monitoring across AI infrastructure.

Maintaining Security Throughout the Infrastructure Lifecycle

Infrastructure security does not end when a system enters production.

Devices move through manufacturing, provisioning, deployment, operation, updates, recovery, and eventual reassignment or decommissioning. Each transition introduces operational considerations that organizations must manage.

BlueField incorporates security protections throughout these stages, including secure provisioning, authenticated firmware updates, rollback protection and device attestation.

These mechanisms help establish and maintain platform integrity as infrastructure evolves.

Organizations can complement these protections with Eclypsium’s lifecycle assessment and monitoring capabilities to maintain component visibility, detect threats, malware and vulnerabilities, evaluate firmware risks and identify configuration changes over time.

This can support repeatable operational practices, including establishing an approved configuration before deployment, monitoring infrastructure during operation and reassessing relevant device state after updates or recovery. 

In practice, that means treating each DPU, GPU and management controller as a first-class asset with its own firmware versions, configuration and owner, bringing it into vulnerability management alongside the host operating system, and including management-interface telemetry such as baseboard management controller and Redfish logs in security monitoring. Because these components persist across operating system reinstalls, reassessment should also follow incident response and precede reassigning hardware to a new tenant.

Different mechanisms contribute different forms of assurance. Secure boot authenticates boot components, attestation provides evidence about measured platform state and configuration assessment helps operators evaluate how systems are deployed and managed.

Each of these is necessary, and none is sufficient on its own. Boot-time measurements confirm how a system started, not how it is behaving now, and an integrity check on a model file confirms the artifact on disk, not the copy running in memory. Continuous runtime verification can help detect runtime changes. Collecting the same state from independent vantage points, such as host configuration of hardware settings, PCIe topology, management controller firmware and change history, forces an attacker to keep every view consistent, which makes compromise substantially harder to hide.

Advancing Infrastructure Security Through Research and Collaboration

Security is a continuous process of engineering, evaluation and improvement.

As infrastructure grows more complex, independent security research plays an important role in identifying potential weaknesses, challenging assumptions and advancing industry security practices.

NVIDIA brings deep product expertise, secure development practices and established vulnerability response processes. Eclypsium contributes independent security research and expertise in assessing infrastructure components, firmware and configurations.

These complementary perspectives can help translate security research into practical improvements in product protections, deployment guidance and operational practices.

The purpose of that research is to make the ecosystem stronger. NVIDIA partnered with Eclypsium to demonstrate how compromised AI infrastructure could affect a model and its reasoning while remaining undetected by stored-model integrity checks: the model file, its hash and its signature all remained valid while the model running in memory behaved differently. 

This challenge is not unique to any one vendor or architecture. GPU-based, alternative-accelerator and custom ASIC systems all depend on privileged components, including host processors, accelerator firmware, management controllers, smart NICs and the mechanisms that move model data between them, that sit beneath the model and can reach the memory where it runs.

NVIDIA continues to invest in BlueField security throughout the product lifecycle, evaluating reported findings and delivering updates or guidance as appropriate.

Collaboration across technology providers, cybersecurity partners, researchers and infrastructure operators helps strengthen the broader ecosystem and supports the continued evolution of trusted infrastructure. Through efforts such as the Open Secure AI Alliance, researchers, technology providers and security teams can turn research findings into shared evaluation methods, verification checks and defenses that raise the assurance baseline for AI infrastructure.

Extending Trusted Infrastructure to Agentic AI

The next major computing transformation is already underway.

AI agents are evolving from systems that generate information into autonomous systems capable of reasoning, accessing sensitive data, interacting with tools and taking actions on behalf of people and organizations.

Protecting these systems requires infrastructure that can independently observe agent behavior, govern access, and enforce security policies in real time.

With the NVIDIA OpenShell Reference Architecture, NVIDIA is extending hardware-isolated infrastructure security into the age of autonomous AI.

NVIDIA BlueField-4 provides the infrastructure foundation for NVIDIA Sentry, a unified security software framework built on NVIDIA DOCA. Operating independently of the host and beyond the agent’s reach, NVIDIA Sentry enables out-of-band monitoring of agent behavior and real-time, in-silicon policy enforcement to help detect and contain threats.

This approach complements NVIDIA OpenShell’s software execution boundaries with an independent layer of infrastructure protection.

As organizations deploy agentic AI at scale, the security of the underlying infrastructure becomes even more critical. NVIDIA provides the mechanisms to govern and enforce safe agent behavior. Eclypsium offers additional tools to verify and monitor hardware and firmware across AI infrastructure. 

The result is an operational model for trusted AI: verify the infrastructure, enforce AI execution from independent security boundaries, govern what agents can access and do, and continuously monitor each layer for changes that could break the chain of trust. Together, the companies are continuously evaluating potential attack scenarios and strengthening AI infrastructure security.

NVIDIA Sweeps MLPerf Training and Endpoints as Vera Rubin Debuts With Leading Performance

by

In its MLPerf benchmarks debut, with results released today, the NVIDIA Vera Rubin platform delivers leading performance across training, post-training and agentic inference. 

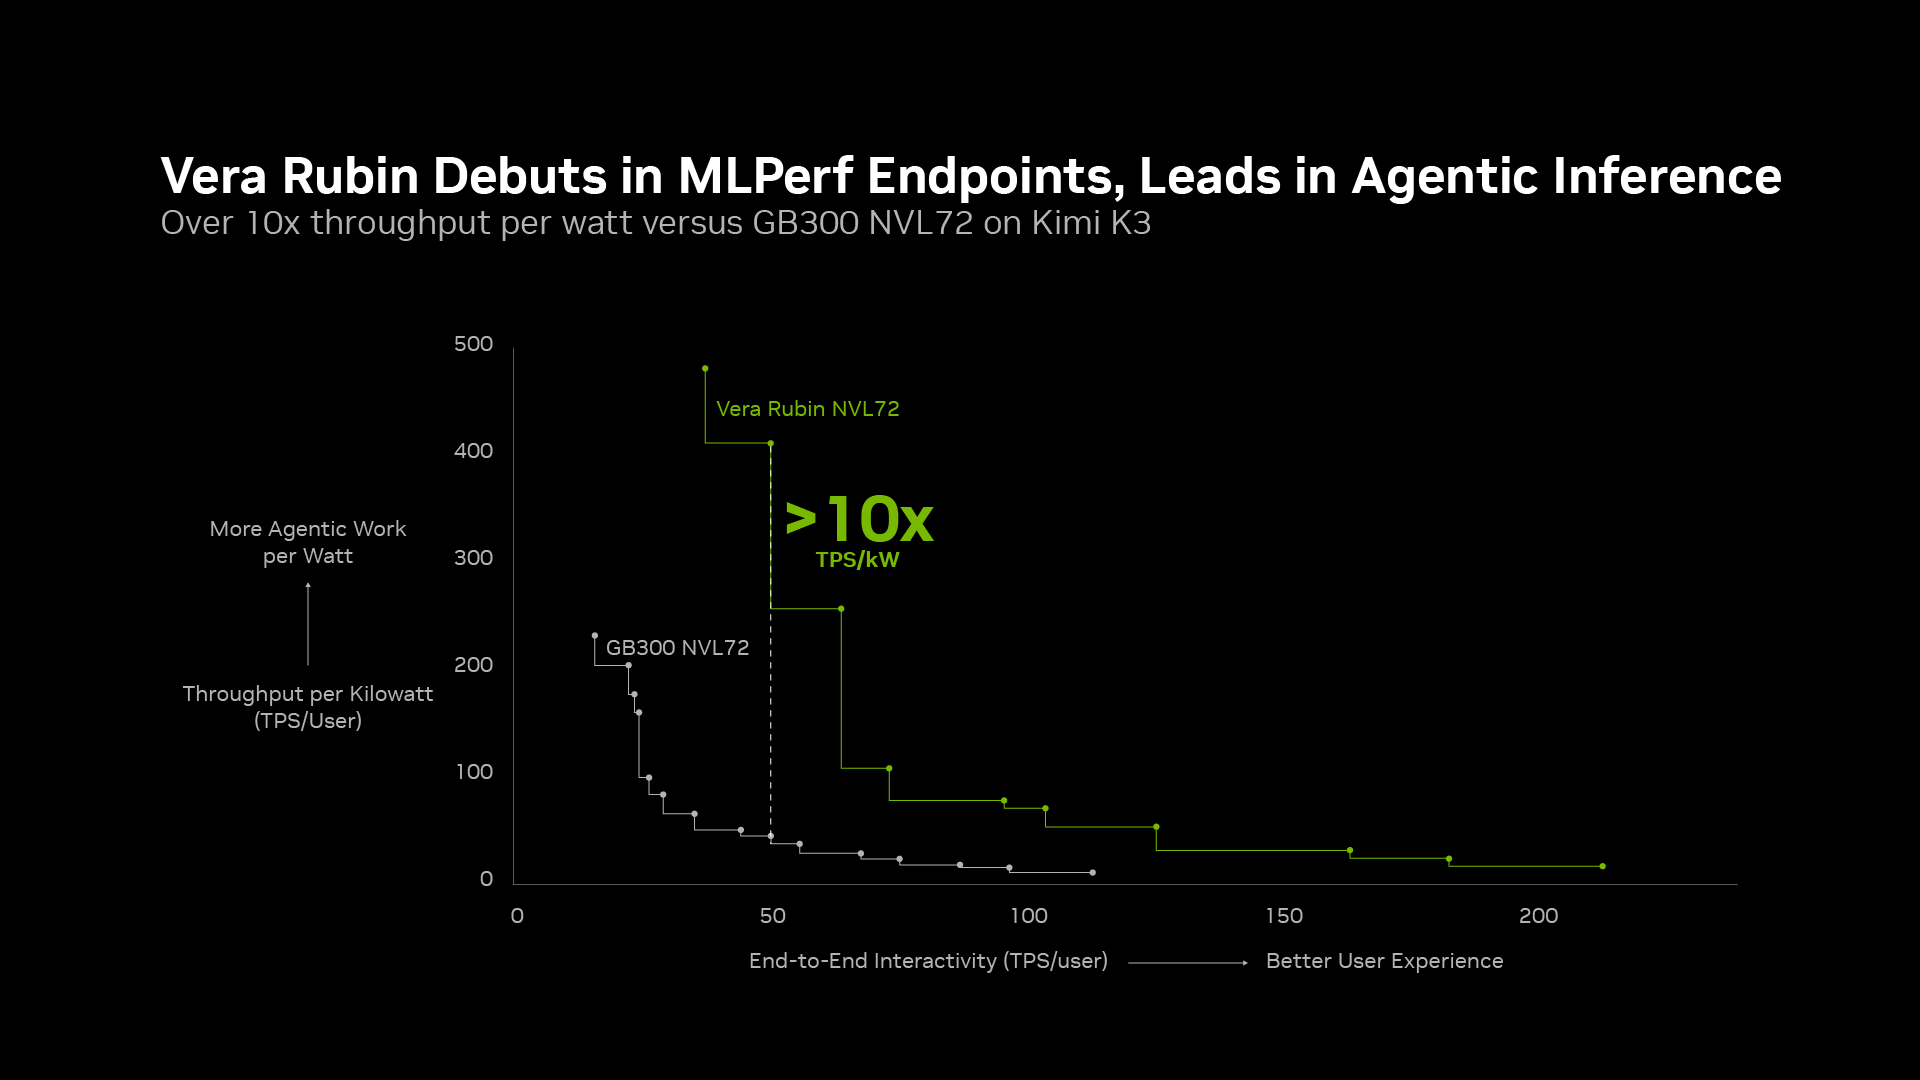
NVIDIA swept every MLPerf Training v6.1 benchmark and, in its first MLPerf Endpoints submission, delivered more than 10x generational gains in throughput per watt for agentic AI — measuring how much agentic work a system delivers with each watt of power. 

These results are just the beginning. Vera Rubin performance will keep climbing through continuous optimization of NVIDIA’s CUDA-powered software stack, so the infrastructure that customers invest in today delivers more value over time.

NVIDIA Sweeps MLPerf Training v6.1

AI agents are now everywhere, writing code, running business workflows, answering customer questions and, as this week’s SC26 conference highlights, advancing scientific research. 

Faster training means smarter agents can reach users sooner, drug discovery models can keep pace with new lab data and fraud-detection models can adapt to new threats faster.

MLPerf Training measures how fast a system can train a range of AI models to a target level of accuracy. 

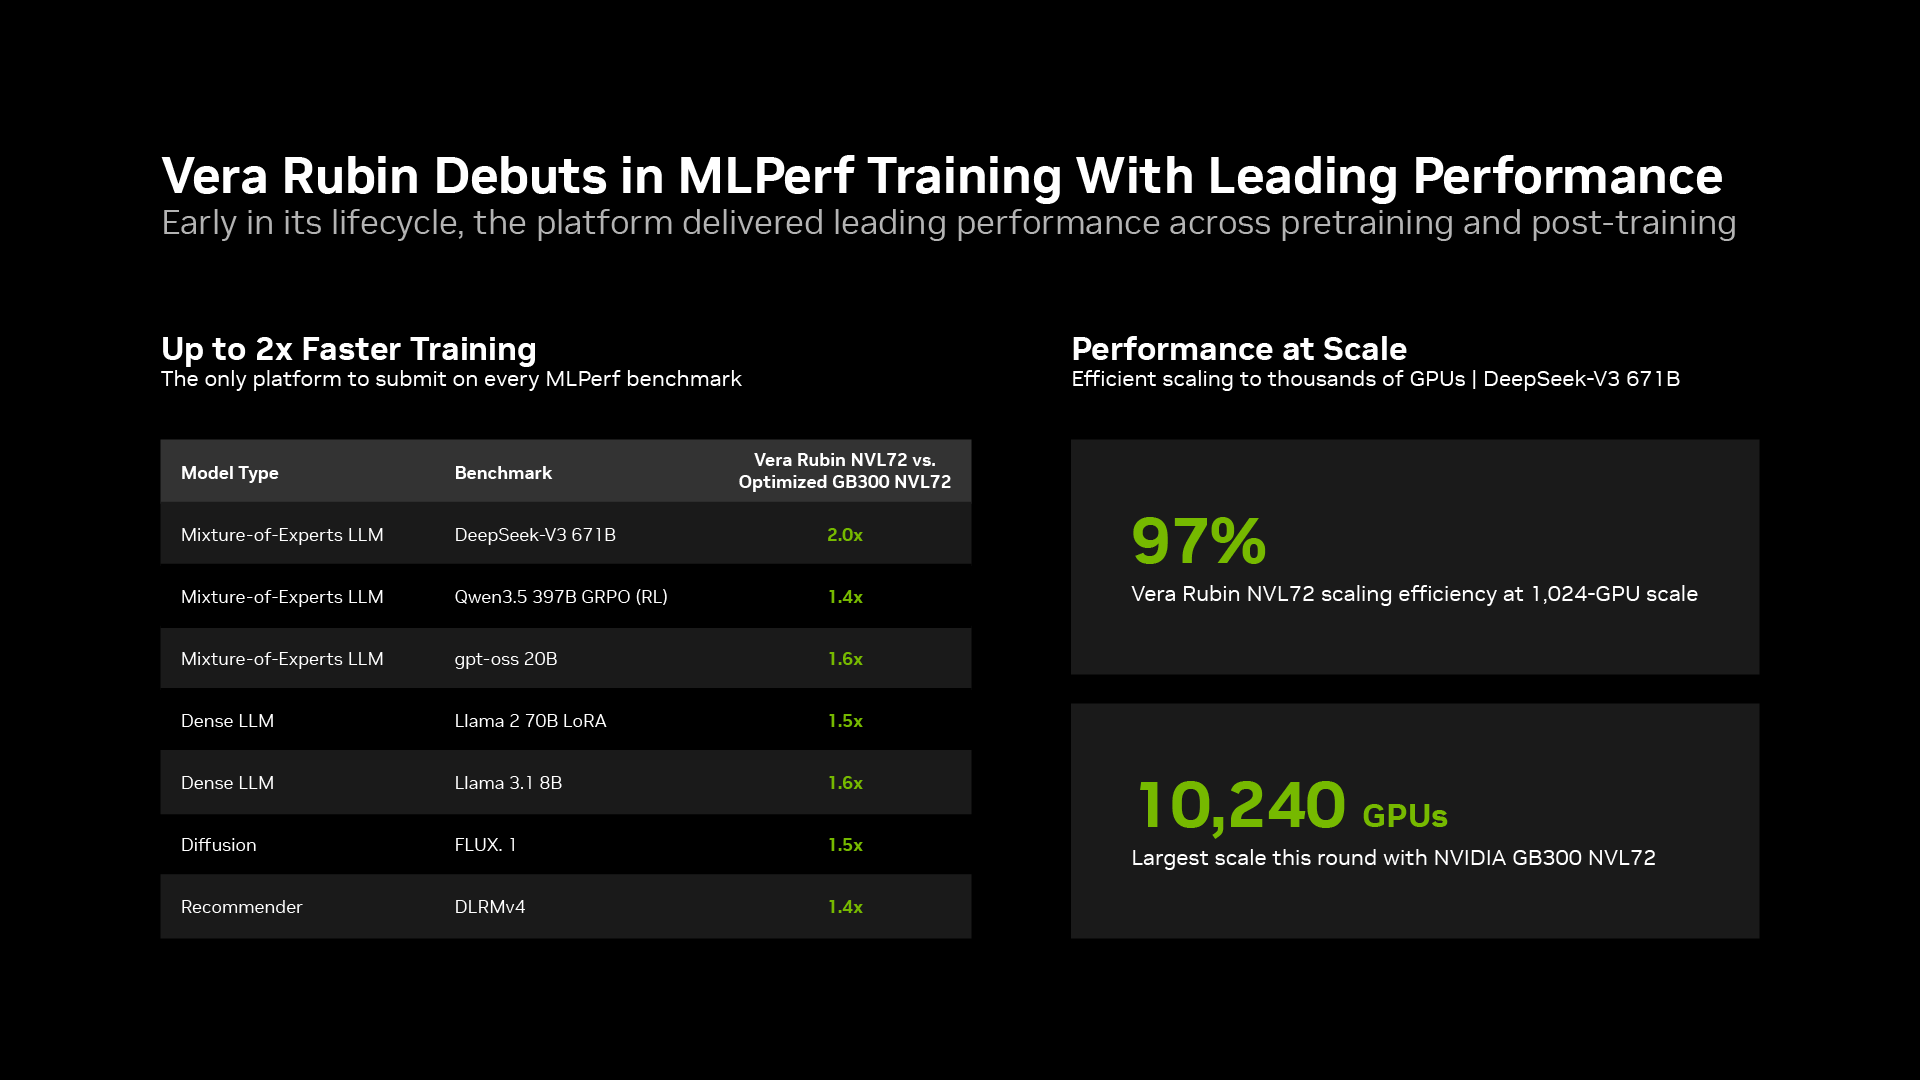
The NVIDIA platform was the only one with results on every benchmark this round, spanning large language models, image generation, recommender systems and reinforcement learning post-training. In its debut, Vera Rubin NVL72 delivered up to 2x more performance per GPU than the highly optimized NVIDIA GB300 NVL72 system — early results that show the pace of generation-over-generation innovation. 

MLPerfTraining v6.1 results retrieved from www.mlcommons.org on Nov 16, 2026, from the following entries: 6.1-0116 , 6.1-0030, 6.1-0135, 6.1-0020, 6.1-0049, 6.1-0123, 6.1-0138, 6.1-0073, 6.1-0124, 6.1-0129 and 6.1-0038. The MLPerf name and logo are trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use is strictly prohibited. See www.mlcommons.org for more information.

NVIDIA also demonstrated performance at scale. On the DeepSeek-V3 benchmark, Vera Rubin NVL72 scaled from 256 to 1,024 GPUs with about 97% efficiency: quadrupling the GPUs cut time to train from 16 minutes to about four. 

NVIDIA also ran the benchmark on 10,240 GPUs with GB300 systems, representing the largest scale in this round. Microsoft Azure matched that scale with 10,240 NVIDIA GPUs with GB200 systems. 

Results at this scale matter because adding GPUs only speeds up training if they can work together efficiently. NVIDIA NVLink scale-up networking connects the GPUs within each system so they act as one, while NVIDIA Quantum-X800 InfiniBand and Spectrum-X Ethernet scale-out networking link those systems across the data center. Combined with optimized software, this keeps thousands of GPUs working in concert, helping developers build more intelligent models while cutting training times.

NVIDIA Vera Rubin Leads Agentic Inference on MLPerf Endpoints

An AI agent for travel that plans and books a whole trip — or an IT agent that finds and fixes a problem before anyone files a ticket — may reason, call tools and check its work many times to finish a single task. 

Each of those steps generates tokens. Because AI data centers are limited by power, the more tokens a system can generate each second for every watt of power, the more agents it can serve and the more value it creates. 

MLPerf Endpoints tests systems on real agentic coding and enterprise workflows, and checks that the agents still complete their tasks correctly. NVIDIA Vera Rubin leads across all of its agentic benchmarks.

For example, in a provisional result for Kimi K3, a large open model built for agentic workflows, Vera Rubin NVL72 systems deliver more than 10x the throughput per watt of NVIDIA GB300 NVL72 at the same response speed. 

MLPerf® Endpoints v1.0, Kimi K3, Standardized division, Available category, published November 9, 2026. NVIDIA Vera Rubin NVL72, 32 accelerators, result 1.0.1.kimi-k3.agentic_combined.1p, run 9: concurrency = 1,024 queries, TTFT P90 = 4,673.9 ms, system TPS= 41,414.2 tokens/sec, E2E average interactivity = 50.4 tokens/sec per user, operating power = 100.89 kW. NVIDIA GB300 NVL72, 48 accelerators, result1.0.0.kimi-k3.agentic_combined.1, run 6: concurrency = 48 queries, TTFT P90 = 2,305.1 ms, system TPS= 2,210.4 tokens/sec, E2E average interactivity = 56.2 tokens/sec per user, operating power = 60 kW. Comparison based on throughput per kilowatt at a shared minimum E2E average interactivity of 50 tokens/sec per user. Retrieved from endpoints.mlcommons.org on November 9, 2026. GB300 results verified by MLCommons Association. For the provisional Vera Rubin results: pending MLCommons Association verification, results are subject to change pending peer review. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use is strictly prohibited. See www.mlcommons.org for more information.

Every AI service has to balance serving many users at once against responding quickly to each one. Vera Rubin shifts that entire curve, serving more users while responding faster. 

Leadership Across Benchmarks and Workloads

NVIDIA partners participated extensively in MLPerf Training, with submissions from 20 organizations: ASUS, Azure, Cisco, CoreWeave, Crusoe, Dell Technologies, Firmus, Giga Computing, Google Cloud, HPE, Inventec, Krai, Lambda, Nebius, Oracle, Quanta Cloud Technology (QCT), Supermicro, TTA and the University of Florida. 

Their submissions show how NVIDIA’s programmable platform, with open source libraries and frameworks, lets a vast ecosystem of partners innovate and optimize AI training performance.

The lead extends beyond MLPerf. 

Vera Rubin also delivers leading performance on independent benchmarks including SemiAnalysis AgentX and Artificial Analysis AgentPerf, showcasing how the same NVIDIA infrastructure can productively run everything from pretraining and post-training to agentic inference, as well as workloads beyond AI, such as the high-performance computing showcased at SC26 this week. 

Dive deeper into the results in the MLPerf Training and MLPerf Endpoints technical blogs.